

An experiment is reproducible when someone else can rerun it later and get the same numbers, or explain exactly why they differ. For vector search and training, that means pinning five things together: the data version (a lake snapshot and a Milvus collection snapshot), the embedding model and preprocessing, the index and search configuration, the query and label set, and the code and environment. Record identifiers for all five with every result, and keep the underlying data alive for as long as the result might need to be rerun.
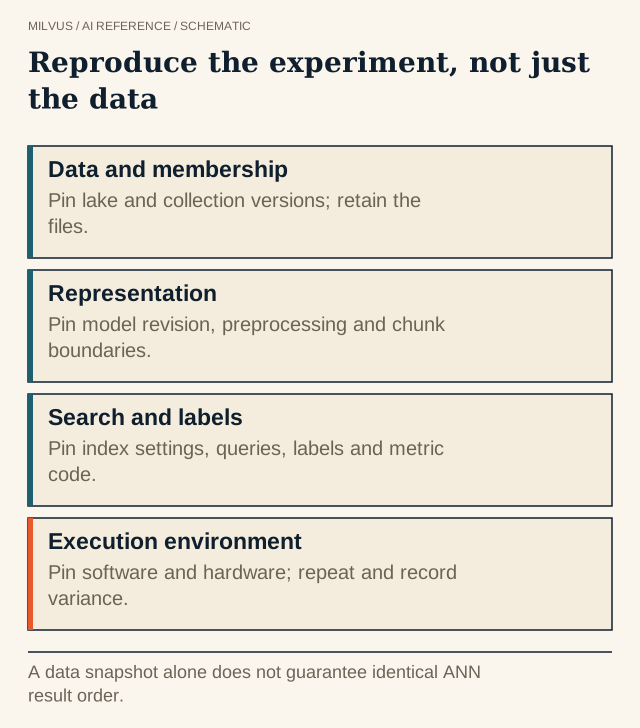 Reproduce the experiment, not just the data. A data snapshot alone does not guarantee identical ANN result order.
Why are vector experiments hard to reproduce?
In ordinary ML, the dataset and the model are the main moving parts. Retrieval adds more, and they change independently:
- Source documents are edited or deleted.
- Chunking rules change, which changes what an embedding even refers to.
- A new encoder revision produces vectors in a different space.
- Index parameters (
M,efConstruction,nlist) and search parameters (ef,nprobe) shift recall. - Approximate search is not exact: recall below 100% means a few results can differ between builds.
- Relevance labels are corrected over time.
A notebook timestamp captures none of this. If last month’s recall@10 was 0.91 and today’s is 0.88, you need to know which of these changed.
What should an experiment record contain?
| Component | Record | Example |
|---|---|---|
| Source data | Lake table and snapshot or version ID | Iceberg snapshot 5937117119577207000 |
| Serving data | Milvus collection and snapshot name | docs_eval_2026_10_01 |
| Representation | Encoder name and revision, chunking settings | bge-m3@v1, 512 tokens, 64 overlap |
| Index and search | Index type, build and search parameters, metric | HNSW, M=16, ef=128, COSINE |
| Evaluation | Query set version, relevance judgments, metric code | qset-v7, qrels-v7, recall@10 |
| Training selection | Manifest of IDs, revisions, splits, weights | train-manifest-2026-10-01.parquet |
| Environment | Git commit, library versions, hardware | a1b2c3d, pinned client and library versions |
Store this record next to the results, not in someone’s head.
Use Milvus snapshots to pin the serving state
Milvus 3.0 adds collection snapshots: point-in-time, read-only images of a collection that reference existing segment, deletion-log, and index files rather than copying vector data. A snapshot captures the schema, partition layout, index metadata, and segment data at creation time, which is exactly what an evaluation run needs to pin.
The snapshot management API is short:
client.flush(collection_name="docs")
client.create_snapshot(
    collection_name="docs",
    snapshot_name="docs_eval_2026_10_01",
    description="Baseline for bge-m3 v1 vs v2 comparison",
)

# Later: restore the same data and index files as a new collection
job_id = client.restore_snapshot(snapshot_name="docs_eval_2026_10_01", collection_name="docs_eval_replay")
print(client.get_restore_snapshot_state(job_id=job_id))
A few properties matter for experiments:
- Restore creates a new collection in the same cluster, with the same schema, shard count, and partitions. Restoration copies segment files directly rather than re-inserting data, so it is fast.
- Snapshots are immutable, which is what you want for a baseline.
- Referenced files are kept. Milvus does not garbage-collect segment or index files referenced by a snapshot until you drop it. That protects reproducibility but costs storage, so drop snapshots you no longer need with
drop_snapshot(). - Pins can expire on their own.
pin_snapshot_data()takes attl_secondsvalue, useful for keeping a snapshot’s data available for the duration of a long offline job. - TTL can interfere. If the collection uses a time-to-live, restoring old data may expire immediately; adjust or disable TTL on the restored collection.
What a snapshot does and does not freeze
A snapshot pins the data and index files. It does not make an approximate search deterministic. Two runs against the same restored collection can still return slightly different top-k lists, because ANN search depends on things outside the snapshot: how segments are loaded and distributed across query nodes and replicas, the order in which per-segment results are merged, ties between equal scores, search parameters such as ef or nprobe that were left at a default, and, on a live collection, new writes in growing segments or compaction rewriting segments after restore.
So define reproducibility at the level you need:
- Metric-level (recall@k, nDCG within a small tolerance) is the realistic target for ANN evaluations. Record the search parameters explicitly instead of relying on defaults.
- Result-level (identical IDs in identical order) requires exact search over a frozen collection, for example a FLAT index, no writes after restore, and a deterministic tie-break on primary key in your evaluation code.
Snapshots are designed for short- and medium-term rollback and experimentation (days to weeks). For long-term disaster recovery, use a backup stored independently; see backup and recovery planning.
Pin the lake side too
If the data lives in a lake, pin it there as well. Iceberg snapshot IDs and Lance dataset versions give you time travel to the exact rows an experiment used. For an Iceberg-backed external collection, the snapshot ID is part of the collection’s configuration, so recording it ties Milvus’s view to a named table state; see searching Iceberg tables with Milvus.
Retention is the catch. Iceberg’s snapshot expiration and orphan-file cleanup will eventually delete files an old experiment depends on, and a saved snapshot ID is useless once its files are gone. Tag or retain the snapshots that back published results, and set the retention window deliberately rather than inheriting the default.
Change one variable at a time
Reproducibility pays off when comparisons are clean:
- Comparing embedding models? Hold the source snapshot, chunking, query set, and labels fixed; change only the encoder.
- Comparing data improvements? Hold the encoder fixed; change only the source version.
- Tuning an index? Compare against an exact FLAT baseline on the same snapshot, so recall is measured against ground truth rather than another approximation.
- Training on retrieved data? Save the selection manifest (IDs, revisions, splits) rather than the query that produced it; rerunning the query on newer data will select different rows.
Prove it by replaying
The real test is a replay: after the original environment is gone, restore the Milvus snapshot, check out the code commit, load the recorded model revision, and rerun the evaluation. Compare metrics against the original within a stated tolerance, and compare top-k membership as an overlap rate rather than expecting identical lists. Small differences from ANN nondeterminism are expected; large ones point at an unrecorded dependency. Doing this once per quarter catches gaps in your records long before an auditor or a paper reviewer does.
Related reading
- How do you evaluate retrieval quality?
- How should you benchmark vector search performance?
- How do you build an evaluation set for agentic and vector search?
- How should you refresh a Milvus external collection safely?
Sources
- Milvus snapshots
- Manage snapshots
- Iceberg table maintenance: snapshot expiration
- Apache Iceberg specification
- Explore end-to-end evaluation notebooks in the Milvus Bootcamp.



