

To evaluate retrieval in a RAG or search system, run a fixed set of representative queries, compare the returned results with relevance judgments that say which passages actually answer each query, and summarize with rank-based metrics: recall@k (did we find the relevant passages?), precision@k (how much of what we returned is relevant?), MRR (how high is the first relevant hit?), and nDCG@k (is the ranking order right, given graded relevance?). Keep these separate from ANN index recall and from answer-quality metrics such as faithfulness, because each one diagnoses a different layer.
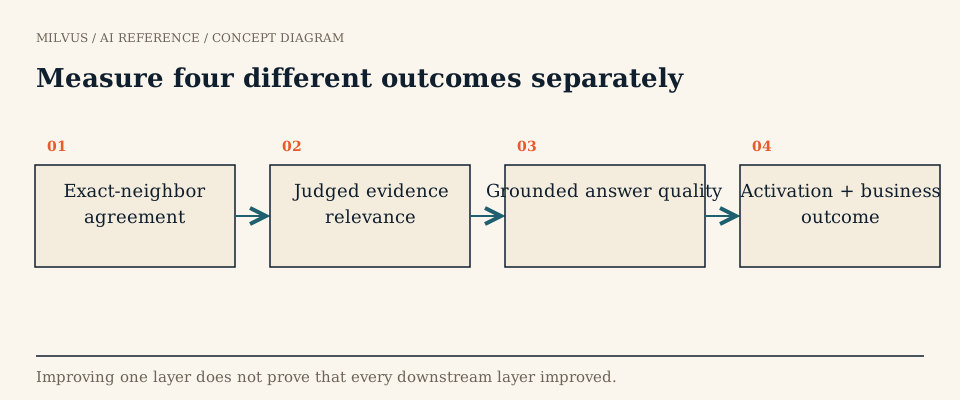 Measure four different outcomes separately
What do you need before computing any metric?
Three things, held fixed while you compare systems:
- Queries that look like real traffic, including exact identifiers, paraphrases, rare entities, filtered queries, and some with no answer in the corpus.
- Relevance labels (qrels): for each query, the IDs of passages that are relevant, ideally graded (for example 0 = not relevant, 1 = partially, 2 = fully answers).
- A frozen corpus snapshot and top-k, so a score change comes from the system, not from the data moving underneath it.
How to sample queries, label them, and keep the set honest over time is its own topic, covered in how to build an evaluation set.
The core retrieval metrics, with formulas
Let R be the set of relevant passages for a query and k the number of results you consider.
| Metric | Formula (per query) | Question it answers | Notes | ||
|---|---|---|---|---|---|
| Precision@k | (relevant results in top k) / k | How much of the context is useful? | Penalizes noise sent to the LLM | ||
| Recall@k | (relevant results in top k) / \ | R\ | Did we find the evidence? | The most important RAG retrieval metric | |
| Hit rate@k | 1 if any relevant result is in top k, else 0 | Did we find at least one? | Fine when one passage suffices | ||
| F1@k | 2·P·R / (P + R) | Balance of the two | Rarely needed alone | ||
| Reciprocal rank | 1 / rank of first relevant result (0 if none) | How quickly does good evidence appear? | MRR is its mean over queries | ||
| Average precision | sum of precision@i over the ranks i that hold a relevant result, divided by \ | R\ | Are all relevant results ranked early? | MAP is its mean over queries | |
| nDCG@k | DCG@k / IDCG@k | Is the order right, with graded relevance? | 1.0 means ideal order |
For nDCG, the discounted cumulative gain at k is
DCG@k = Σ (i = 1..k) (2^rel_i − 1) / log2(i + 1)
where rel_i is the graded label of the result at rank i. IDCG@k is the same sum for the ideal ordering of the labeled results, so nDCG@k always falls between 0 and 1. (A simpler variant uses rel_i instead of 2^rel_i − 1 in the numerator; report which one you use.)
Average every metric over all queries, and also report it per slice. A global average can hide a category that is completely broken.
A worked example
A query has three relevant passages: A (grade 2), B (grade 1), C (grade 1). The system returns five results: [A, X, B, Y, Z].
- Precision@5 = 2/5 = 0.40
- Recall@5 = 2/3 = 0.67 (C was missed)
- Hit rate@5 = 1
- Reciprocal rank = 1/1 = 1.0 (A is first)
- DCG@5 = (2²−1)/log2(2) + (2¹−1)/log2(4) = 3/1 + 1/2 = 3.5
- IDCG@5, ideal order A, B, C = 3/1 + 1/log2(3) + 1/log2(4) ≈ 3 + 0.631 + 0.5 = 4.131
- nDCG@5 = 3.5 / 4.131 ≈ 0.85
If a second query’s first relevant result appeared at rank 3, its reciprocal rank would be 0.33, and MRR across the two queries would be (1.0 + 0.33) / 2 ≈ 0.67.
Which metric should you optimize for RAG?
Pick k to match what the generator actually sees. If you rerank 50 candidates down to 5, measure recall@50 for the first-stage retriever (did the evidence make it into the candidate pool?) and recall@5 or nDCG@5 after reranking (did it make it into the prompt?).
- Recall@k first. If the evidence is not retrieved, nothing downstream can fix it.
- nDCG@k or MRR when position matters, for example when you show results to users or when the LLM tends to favor the first passages.
- Precision@k when context is expensive or noisy passages mislead the model.
- Hit rate for single-answer lookups such as "which document defines X".
The BEIR benchmark, widely used for comparing retrieval models, reports nDCG@10 as its headline number, with recall and MAP alongside.
How is this different from ANN recall?
Vector databases also talk about "recall", but it means something else. ANN recall compares approximate results from an index such as HNSW or IVF with the exact nearest neighbors from a brute-force search on the same embeddings. It tells you how much accuracy the index trades for speed. Relevance recall compares results with human or LLM judgments of usefulness. It tells you whether the embedding model, chunking, filters, and fusion find the right evidence.
An index can reach 0.99 ANN recall while relevance recall stays at 0.60, because the exact nearest neighbors of a poor embedding are still the wrong passages. Measure both: tune index parameters (ef, nprobe) against a FLAT baseline, and tune models and pipeline against relevance labels.
RAG-specific metrics beyond the retriever
Once retrieval is measured, check how the generator uses it. The Ragas framework defines LLM-judged metrics that do not always need reference answers:
- Context precision: are the relevant retrieved chunks ranked above the irrelevant ones?
- Context recall: does the retrieved context contain the information in the reference answer?
- Faithfulness: are the answer’s claims supported by the retrieved context?
- Answer relevancy: does the answer address the question?
These complement rather than replace labeled recall@k: LLM judges are fast but should be spot-checked against human labels. Milvus has an integration guide for Ragas that computes all four on a Milvus-backed pipeline.
Computing metrics on Milvus search results
Run each query through the same search call your application uses, keep the IDs, and score them against the qrels:
import math
from pymilvus import MilvusClient

client = MilvusClient("rag_demo.db")

def ndcg_at_k(ranked, grades, k):
    dcg = sum((2 ** grades.get(d, 0) - 1) / math.log2(i + 2) for i, d in enumerate(ranked[:k]))
    ideal = sorted(grades.values(), reverse=True)[:k]
    idcg = sum((2 ** g - 1) / math.log2(i + 2) for i, g in enumerate(ideal))
    return dcg / idcg if idcg else 0.0

k, totals = 10, {"recall": 0, "mrr": 0, "ndcg": 0}
for q in eval_set:                       # each q: {"text", "filter", "grades": {chunk_id: grade}}
    hits = client.search(collection_name="docs", data=[embed(q["text"])],
                         filter=q.get("filter", ""), limit=k, output_fields=["chunk_id"])[0]
    ranked = [h["entity"]["chunk_id"] for h in hits]
    relevant = {d for d, g in q["grades"].items() if g > 0}
    totals["recall"] += len(relevant & set(ranked)) / len(relevant)
    totals["mrr"] += next((1 / (i + 1) for i, d in enumerate(ranked) if d in relevant), 0)
    totals["ndcg"] += ndcg_at_k(ranked, q["grades"], k)

print({m: round(v / len(eval_set), 3) for m, v in totals.items()})
Label at the level you retrieve. If you change chunking, chunk IDs change, so label relevance by document and character span, or by document ID, and map to chunks at scoring time. Decide in advance how duplicates and near-duplicate chunks count, or overlapping chunks will inflate precision.
Reading results without fooling yourself
- Unlabeled is not irrelevant. If a returned passage has no label, inspect it; incomplete labels make good systems look worse. Pooling (labeling the union of top results from several systems) reduces this bias.
- Slice the report by query type, language, tenant, and filtered versus unfiltered queries.
- Hold out a test split. Tune chunking, fusion weights, and rerankers on a development split, then confirm once.
- Report quality with cost. Compare configurations at the same latency and budget: a reranker that adds 0.03 nDCG for 200 ms may or may not be worth it.
A typical improvement loop is: measure recall@k, fix the biggest slice failure (often by adding hybrid search for identifier queries or a reranker for ordering), re-measure, then check faithfulness. To set up a pipeline you can measure, start with Build RAG with Milvus, or pick a runnable application from the Milvus Bootcamp.
Related reading
- How do you build an evaluation set for agentic and vector search?
- What is retrieval-augmented generation (RAG)?
- How do you choose chunk size for RAG?
- What are hard negatives in retrieval training, and how can you mine them?
- How should you benchmark vector search performance?



