

Embeddings catch the duplicates that hashing misses: records that say the same thing in different words. You encode each record with a model such as a Sentence Transformers checkpoint, then treat any pair whose cosine similarity exceeds a calibrated threshold (often somewhere around 0.9 to 0.95, depending on the model) as a candidate duplicate. At small scale that is a pairwise comparison; at millions of records you need an approximate nearest-neighbor index so each record only checks its closest neighbors. Milvus covers both halves of a modern dedup pipeline: MinHash signatures with a MINHASH_LSH index for lexical near-duplicates, and dense vectors with range search for semantic ones.
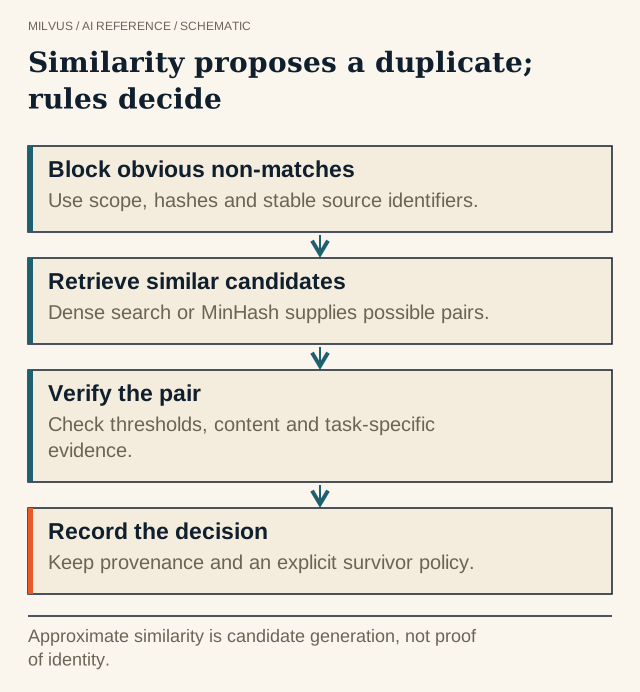 Similarity proposes a duplicate; rules decide. Approximate similarity is candidate generation, not proof of identity.
Exact, near-duplicate, and semantic duplicates
Duplicates come in three kinds, and each has a cheapest reliable detector.
| Kind | Example | Detector | Cost |
|---|---|---|---|
| Exact | Same file ingested twice | Hash of normalized content (MD5, SHA-256) | Trivial |
| Near-duplicate (lexical) | Same article with a different footer, whitespace, or a few edited words | MinHash signatures + LSH, Jaccard similarity on shingles | Low |
| Semantic | A paraphrase, a translated summary, a reworded FAQ answer | Dense embeddings + cosine similarity | Highest |
Run them in that order. Hashing removes the bulk of trivial copies for almost nothing, MinHash clears templated and lightly edited pages, and the embedding stage only has to reason about what is left. Each stage should tag the pairs it proposes so a bad removal can be traced to the method and threshold that caused it. Large-scale curation toolkits follow the same staging, and research such as SemDeDup found that removing semantic duplicates from a web-scale image-text corpus could drop about half the data with minimal accuracy loss, which is why the embedding stage is worth the compute.
How does embedding-based deduplication work?
- Normalize and chunk consistently. Dedup units must match the unit you train on or retrieve: whole documents, passages, or Q&A pairs. Mixing units hides duplicates.
- Embed with one model and normalize. Use the same model revision for every record and L2-normalize so inner product equals cosine similarity.
- Find candidate pairs. For each record, retrieve neighbors above the similarity threshold. Brute force is O(N²); clustering first (k-means, then compare only within each cluster, as SemDeDup does) or an ANN index brings it down to roughly O(N · k).
- Group candidates. Connect pairs into groups, but guard against chaining: A≈B and B≈C does not make A≈C. Prefer grouping around a chosen representative over taking full connected components.
- Pick a survivor and record the decision. Keep the most authoritative, recent, or highest-quality member, and record the merged IDs, the stage, the score, and the threshold.
Sentence Transformers ships paraphrase_mining and community_detection utilities that implement steps 3 and 4 in memory, which is fine for tens or hundreds of thousands of records. Beyond that, or when new records keep arriving, a persistent vector index is the better home for step 3.
How to deduplicate with Milvus
Semantic duplicates: range search over a dense vector field
Store the normalized embedding in a FLOAT_VECTOR field indexed with HNSW or an IVF variant using the COSINE metric. Instead of keeping the top k regardless of score, keep only candidates inside a similarity band with range search. Range search still returns at most limit results and only the neighbors the ANN index visits, so set limit comfortably above the largest duplicate group you expect and re-query with a higher limit whenever a result comes back full. For COSINE and IP, radius is the exclusive lower bound and range_filter the inclusive upper bound:
res = client.search(
    collection_name="docs",
    data=[vec],
    limit=50,
    filter=f"id != {rec_id}",
    search_params={"metric_type": "COSINE", "params": {"radius": 0.92, "range_filter": 1.0}},
    output_fields=["id", "source", "updated_at"],
)
Everything returned is a candidate duplicate of rec_id. Batch many query vectors per call when sweeping a whole collection. For incremental ingestion, run the same search for each new record before inserting it: if a near-identical record already exists, skip the insert or link the new record to the existing one. That turns deduplication from a periodic batch job into an ingest-time check.
Lexical near-duplicates: MinHash and MINHASH_LSH
Milvus 3.0 adds a MINHASH function that turns a VARCHAR field into a MinHash signature stored in a BINARY_VECTOR field (the dimension is 32 * num_hashes), and a MINHASH_LSH index with the MHJACCARD metric for fast Jaccard-similarity lookup:
schema.add_function(Function(
    name="minhash_fn",
    function_type=FunctionType.MINHASH,
    input_field_names=["text"],
    output_field_names=["mh_sig"],
    params={"num_hashes": 256, "shingle_size": 3},
))
Index parameters such as mh_lsh_band trade recall for speed, and the search parameter mh_search_with_jaccard re-scores candidates with exact Jaccard similarity. Keeping both mh_sig and the dense vector on the same row lets one collection serve both stages. The MINHASH_LSH guide covers tuning.
Keep dedup decisions in the collection
Add a dup_status field (unique, duplicate, review) and a dup_of field holding the survivor’s primary key, and write decisions with upsert. On Milvus 2.6.2 and later, partial_update=True updates just those fields without resending the vector. Serving queries then filter with dup_status != "duplicate", while the excluded rows remain available for audit. When the policy calls for physical removal, client.delete(collection_name="docs", ids=[...]) removes them by primary key. For search results that should show only one hit per source document, grouping search on a doc_id field handles display-time redundancy without deleting anything.
How do you choose the similarity threshold?
There is no universal number. Cosine scores are not comparable across models, and the right cut depends on whether a false merge or a missed duplicate costs more. Calibrate it:
- Sample a few hundred candidate pairs across the similarity range, label them duplicate or not, and plot precision and recall against threshold.
- Include hard cases: two contract versions differing in one clause, two product pages differing only in size, two dashcam clips that look alike but capture different events. These are the pairs a loose threshold wrongly merges.
- Run once without removing anything and look at the distribution of nearest-neighbor similarities; a visible bump near the top usually marks the duplicate population.
- Set separate thresholds per stage and per content type if needed.
Where embedding deduplication goes wrong
Embeddings measure topical and semantic closeness, not factual identity. Two passages about the same API that give different version numbers can score 0.97. Numbers, negations, dates, and named entities are exactly the details embeddings compress away, so high-stakes corpora (legal, medical, financial) benefit from a second check, such as a cross-encoder or a field-level comparison, before merging. Very short texts also collide easily, so set a minimum length for the semantic stage or use a stricter threshold for short records. Related problems are covered in entity resolution with vector search and how data quality affects vector retrieval.
Next step
Create a collection with both a dense vector and a MinHash field, load a sample with the Milvus Quickstart, and compare which duplicates each stage finds. The broader workflow around these decisions is covered in data curation with vector search.


