

Open source, for real
Apache 2.0 and governed by the LF AI & Data Foundation. Hundreds of contributors build it in the open on GitHub.
Milvus is a free, Apache 2.0 open source vector database from the LF AI & Data Foundation, written in Go and C++ for high-performance search at scale. Start with pip install, grow to tens of billions of vectors on Kubernetes, and keep the same API.
Apache 2.0 and governed by the LF AI & Data Foundation. Hundreds of contributors build it in the open on GitHub.
The Knowhere engine picks SSE, AVX2, AVX512 or ARM instructions at runtime, and GPU indexes such as CAGRA run on NVIDIA hardware.
Storage and compute are separated. Stateless query, streaming and data nodes scale independently on Kubernetes to tens of billions of vectors.
NVIDIA, Salesforce, Walmart, eBay, IBM and Reddit are on the Milvus adopter wall; Meituan runs 10B+ vectors on self-hosted Milvus.
Zilliz Cloud is fully managed Milvus: the same API, with no clusters to size, upgrade or scale.
Try Zilliz Cloud freeOfficial SDKs and a REST API cover the common stacks and AI frameworks.
Choose the index per collection for recall, latency and memory, and combine vector search with filters or full-text search.
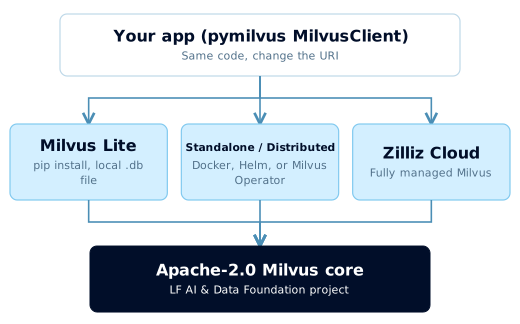
Same engine and API at every size, sized per the install overview. Distributed Milvus installs with the official Helm chart or Milvus Operator.
| Database | License, language | Self-hosted deployment | Vector indexes | Hybrid search (keyword + vector) |
|---|---|---|---|---|
| Milvus | Apache-2.0; Go, C++ | pip (Lite), Docker (Standalone), Kubernetes (Distributed); Zilliz Cloud | HNSW, IVF, DiskANN, SCANN, IVF_RABITQ, GPU_CAGRA | Built-in BM25 and sparse vectors; RRF or weighted ranker |
| Qdrant | Apache-2.0; Rust | Docker single node, cluster; Qdrant Cloud managed | HNSW | Dense + sparse vectors fused with RRF or DBSF |
| Weaviate | BSD-3-Clause core (separate Weaviate License for wl/); Go | Docker, Kubernetes; Weaviate Cloud managed | HNSW, flat, dynamic, HFresh | Vector + BM25F with relative score or ranked fusion |
| Chroma | Apache-2.0; Python, Rust | In-process, client-server; Chroma Cloud managed | HNSW (single node), SPANN (distributed) | Vector search with full-text and metadata filters |
| pgvector | PostgreSQL License; C | Extension in any Postgres, including managed Postgres | HNSW, IVFFlat | Postgres full-text search combined in SQL, e.g. with RRF |
Facts from each project's documentation. Results depend on configuration; run VectorDBBench on your own data.
Milvus Lite ships with pymilvus. No server, no Docker, no account: the database is a local file.
# pip install -U "pymilvus[milvus-lite]"
import random
from pymilvus import MilvusClient

client = MilvusClient("milvus_demo.db")  # Milvus Lite: data lives in this local file
client.create_collection(collection_name="demo", dimension=768)

docs = ["Milvus is an open-source vector database.", "It runs on a laptop or on Kubernetes."]
vecs = [[random.random() for _ in range(768)] for _ in docs]  # swap in your embedding model
client.insert(collection_name="demo",
              data=[{"id": i, "vector": v, "text": t} for i, (v, t) in enumerate(zip(vecs, docs))])

print(client.search(collection_name="demo", data=[vecs[0]], limit=2, output_fields=["text"]))
To move to a server, pass its URI (for example http://localhost:19530) to MilvusClient.
Milvus is: Apache 2.0 permits commercial use, modification and redistribution at no cost, and released code stays Apache 2.0. Milvus is a graduated LF AI & Data Foundation project; Zilliz is its major contributor. You pay only for the infrastructure you run.
Pick by workload. Milvus fits RAG that needs hybrid search, filtering and scale: built-in BM25, partition keys for per-tenant retrieval, and LangChain and LlamaIndex integrations, from a laptop file to a Kubernetes cluster.
Self-hosting Milvus gives full control of data and infrastructure cost; your team runs upgrades, scaling and backups. Zilliz Cloud runs the same engine behind the same MilvusClient API, so moving either way needs no rewrite.
Raw float32 vectors take dimensions × 4 bytes each before index overhead. Milvus cuts that with SQ8 (75% less than FP32), IVF_RABITQ (1-to-32 compression) or DiskANN on NVMe; estimate with milvus.io/tools/sizing.
Yes. Distributed Milvus runs on Kubernetes with replicas and independent scaling. Meituan runs 10B+ vectors on self-hosted Milvus; Read AI serves 20–50 ms retrieval to millions of users.
pip install pymilvus, open a local file, and search. Move to Standalone or Kubernetes as data grows, or hand operations to Zilliz Cloud, with no rewrite.