

Full-text search finds documents by the words they contain. Text is broken into terms by an analyzer, stored in an inverted index that maps each term to the documents containing it, and matching documents are ranked by a relevance function. BM25 (Okapi Best Matching 25) is the standard ranking function: it rewards documents that contain the query’s rarer terms, gives diminishing credit for repeated terms, and adjusts for document length. It has been the default in most search engines for decades and remains a strong baseline next to neural retrieval.
In Milvus, BM25 full-text search is built in. You store raw text in a VARCHAR field, a BM25 function turns it into a sparse vector automatically, and you search with plain query text.
 From words to ranked documents. Lexical overlap and semantic similarity are complementary signals.
How does full-text search work?
A full-text engine does three jobs.
1. Analysis. An analyzer converts text into terms. A tokenizer splits the text, and filters normalize the tokens: lowercasing, removing stop words like “the” or "a", stemming “indexing” and “indexed” to "index", or segmenting languages such as Chinese that do not separate words with spaces. The same analyzer runs on documents and queries, so they agree on what a term is. Analyzer choice quietly decides what can match: if a tokenizer splits HNSW_PQ into hnsw and pq, a search for the full identifier behaves differently than you might expect.
2. Indexing. For each term, the inverted index keeps a posting list: the IDs of documents containing the term and how many times it appears in each. It also tracks corpus statistics, namely the number of documents, each term’s document frequency, and the average document length.
3. Retrieval and ranking. A query reads the posting lists of its terms, so it only ever touches documents that share at least one term with it. Each candidate gets a BM25 score, and the top k are returned. Dynamic pruning algorithms such as WAND and MaxScore skip documents that cannot possibly reach the current top k, which keeps long posting lists fast.
How is the BM25 score calculated?
For a query q and document d, BM25 sums a contribution from each query term t:
score(q, d) = Σ IDF(t) × f(t,d) × (k1 + 1) / ( f(t,d) + k1 × (1 − b + b × |d| / avgdl) )
f(t,d)is how oftentappears ind.|d|is the document’s length in terms, andavgdlis the average length across the collection.IDF(t)is the inverse document frequency. A common form isln(1 + (N − n(t) + 0.5) / (n(t) + 0.5)), whereNis the number of documents andn(t)is how many containt.k1andbare tuning parameters, conventionally 1.2 and 0.75.
Each piece has a clear job.
IDF rewards rare terms. In a corpus of 1,000,000 documents, a term that appears in 100 of them gets an IDF of about 9.2, while a term that appears in 500,000 gets about 0.7. Matching “HNSW” in a technical corpus says much more than matching "index".
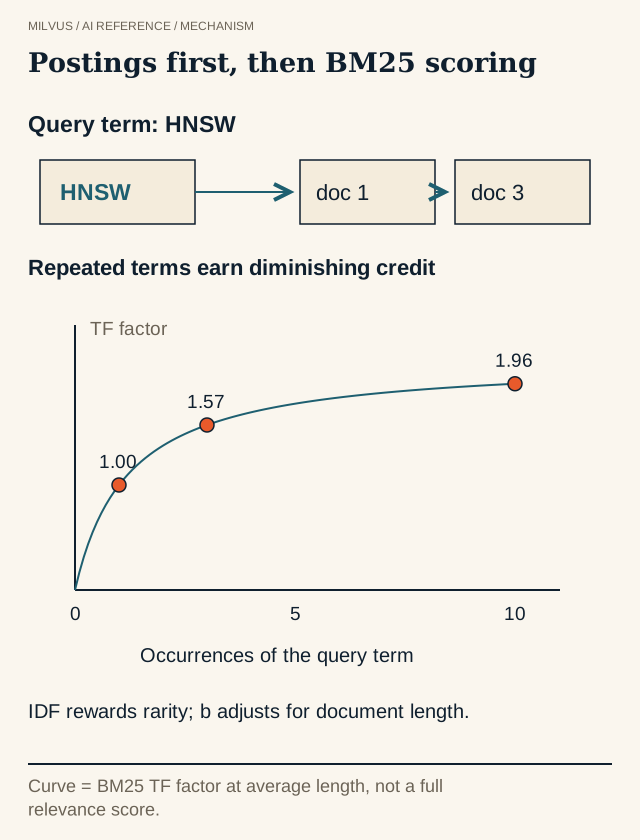
k1 makes term frequency saturate. With k1 = 1.2 and an average-length document, one occurrence of a term earns 1.0 times its IDF, three occurrences earn about 1.57 times, and ten earn about 1.96 times. The ceiling is k1 + 1 = 2.2, no matter how often the word repeats. This is the main difference from raw TF-IDF, where keyword stuffing keeps paying off. A lower k1 saturates faster, which suits short fields like titles; a higher k1 gives more weight to repetition.
b normalizes for length. With b = 0.75, a document twice the average length is treated as if each term occurred noticeably less often, so a long page that mentions a term once does not beat a focused page. At b = 0 length is ignored; at b = 1 term frequency is fully scaled by relative length.
The score is a ranking signal, not a probability. It is only comparable across documents for the same query and corpus, which matters when you later fuse BM25 with vector scores.
BM25 vs TF-IDF vs semantic search
| TF-IDF | BM25 | Dense semantic search | |
|---|---|---|---|
| Matches | Shared terms | Shared terms | Meaning, via embeddings |
| Repeated terms | Linear credit | Saturating credit (k1) | Not applicable |
| Document length | Usually cosine-normalized | Tunable normalization (b) | Not applicable |
| Handles synonyms and paraphrase | No | No | Yes |
| Exact IDs, codes, rare names | Good | Very good | Often weak |
| Needs an ML model | No | No | Yes |
BM25 cannot connect “stale results” with “outdated search output” because the two share no terms. Dense embeddings can, but they often blur exact strings like error codes, SKUs, or function names. That complementary failure pattern is the reason to combine them in hybrid search. For a broader comparison, see how semantic search differs from keyword search.
How do you run BM25 full-text search in Milvus?
Milvus represents BM25 as a sparse vector: each dimension is a term, and the value carries its BM25 weight. You do not compute these vectors yourself. Following the Milvus full-text search guide, you declare a text field with an analyzer, a SPARSE_FLOAT_VECTOR output field, and a BM25 function that links them:
from pymilvus import MilvusClient, DataType, Function, FunctionType

client = MilvusClient(uri="http://localhost:19530")

schema = client.create_schema()
schema.add_field("id", DataType.INT64, is_primary=True, auto_id=True)
schema.add_field("text", DataType.VARCHAR, max_length=8192,
                 enable_analyzer=True,
                 analyzer_params={"type": "english"})
schema.add_field("sparse", DataType.SPARSE_FLOAT_VECTOR)

schema.add_function(Function(
    name="text_bm25_emb",
    input_field_names=["text"],
    output_field_names=["sparse"],
    function_type=FunctionType.BM25,
))

index_params = client.prepare_index_params()
index_params.add_index(
    field_name="sparse",
    index_type="SPARSE_INVERTED_INDEX",
    metric_type="BM25",
    params={
        "inverted_index_algo": "DAAT_MAXSCORE",
        "bm25_k1": 1.2,
        "bm25_b": 0.75,
    },
)
client.create_collection("articles", schema=schema, index_params=index_params)
You insert only the raw text; Milvus analyzes it, updates the corpus statistics, and fills the sparse field. To search, pass the query as text:
res = client.search(
    collection_name="articles",
    data=["HNSW efConstruction memory"],
    anns_field="sparse",
    limit=10,
    output_fields=["text"],
    search_params={"params": {"drop_ratio_search": 0.2}},
)
The relevant index parameters are:
| Parameter | Values | Default | Effect |
|---|---|---|---|
bm25_k1 | [1.2, 2.0] | 1.2 | Term-frequency saturation |
bm25_b | [0, 1] | 0.75 | Length normalization |
inverted_index_algo | DAAT_MAXSCORE, DAAT_WAND, TAAT_NAIVE, BLOCK_MAX_MAXSCORE, BLOCK_MAX_WAND | DAAT_MAXSCORE | Query-processing algorithm over posting lists |
drop_ratio_search (search) | [0.0, 1.0) | optional | Ignores the lowest-weight query terms to speed up search |
The generated sparse vectors are internal: you cannot return the sparse field in output_fields. The sparse inverted index guide explains how this index differs from dense ANN.
Which analyzer should you use?
Milvus ships built-in analyzers including standard, english, chinese, arabic, and thai, and lets you build a custom one from a tokenizer plus filters such as lowercase and stop. See the analyzer overview. Before loading data, run representative text through client.run_analyzer(text, analyzer_params) and look at the tokens. Check product codes, version numbers, hyphenated terms, and mixed-language content. Most “BM25 doesn’t find it” bugs turn out to be analyzer bugs.
When do you need TEXT_MATCH or PHRASE_MATCH instead?
BM25 ranks documents; it does not guarantee that every query term or an exact phrase is present. When you need a hard condition, Milvus offers filter functions on fields created with both enable_analyzer=True and enable_match=True:
TEXT_MATCH(text, 'milvus hnsw')keeps documents containing any of the analyzed terms (combine expressions withandto require all of them). It filters without scoring. See keyword match.PHRASE_MATCH(text, 'product quantization', 0)requires the terms in order, with an optionalslopfor nearby positions. See phrase match.
These can be used as the filter on a BM25 or vector search, so you can require an exact phrase and still rank by relevance.
Where does BM25 fall short?
BM25 does not understand meaning, so it misses paraphrases and synonyms unless the analyzer or query expansion adds them. It also does nothing about cross-language queries and gives no credit for related concepts. Corpus statistics shift as documents are added or deleted, so absolute scores drift over time. And because scores are unbounded and corpus-dependent, they cannot be added directly to cosine similarities. Rank-based fusion such as RRF exists for that reason.
The practical pattern for RAG and enterprise search is to run BM25 and dense retrieval side by side, fuse the candidates, and optionally rerank the shortlist. In Milvus, the BM25 sparse field and a dense vector field can live in the same collection and be queried together with hybrid_search.
To try it, follow the Milvus Quickstart, then add a BM25 function with the full-text search guide. The Milvus Bootcamp has a complete hybrid semantic and full-text search demo.



