

Grafik RAG dengan Milvus


Penerapan model bahasa besar yang semakin meluas menyoroti pentingnya meningkatkan akurasi dan relevansi responsnya. Retrieval-Augmented Generation (RAG) meningkatkan kemampuan model dengan basis pengetahuan eksternal, memberikan informasi kontekstual yang lebih banyak, dan mengurangi masalah seperti halusinasi dan pengetahuan yang tidak memadai. Namun, mengandalkan paradigma RAG sederhana saja memiliki keterbatasan, terutama saat menangani hubungan entitas yang kompleks dan pertanyaan multi-hop, di mana model sering kali kesulitan memberikan jawaban yang akurat.
Memasukkan grafik pengetahuan (KG) ke dalam sistem RAG menawarkan solusi baru. KG menyajikan entitas dan hubungannya secara terstruktur, memberikan informasi pencarian yang lebih tepat, dan membantu RAG menangani tugas tanya-jawab yang kompleks dengan lebih baik. KG-RAG masih berada pada tahap awal, dan belum ada konsensus mengenai cara yang efektif untuk mengambil entitas dan hubungan dari KG atau cara mengintegrasikan pencarian kesamaan vektor dengan struktur graf.
Dalam notebook ini, kami memperkenalkan pendekatan sederhana namun kuat untuk meningkatkan kinerja skenario ini secara signifikan. Ini adalah paradigma RAG sederhana dengan pencarian multi-arah dan kemudian penataan ulang peringkat, tetapi menerapkan Graph RAG secara logis, serta mencapai kinerja terbaik dalam menangani pertanyaan multi-hop. Mari kita lihat bagaimana implementasinya.
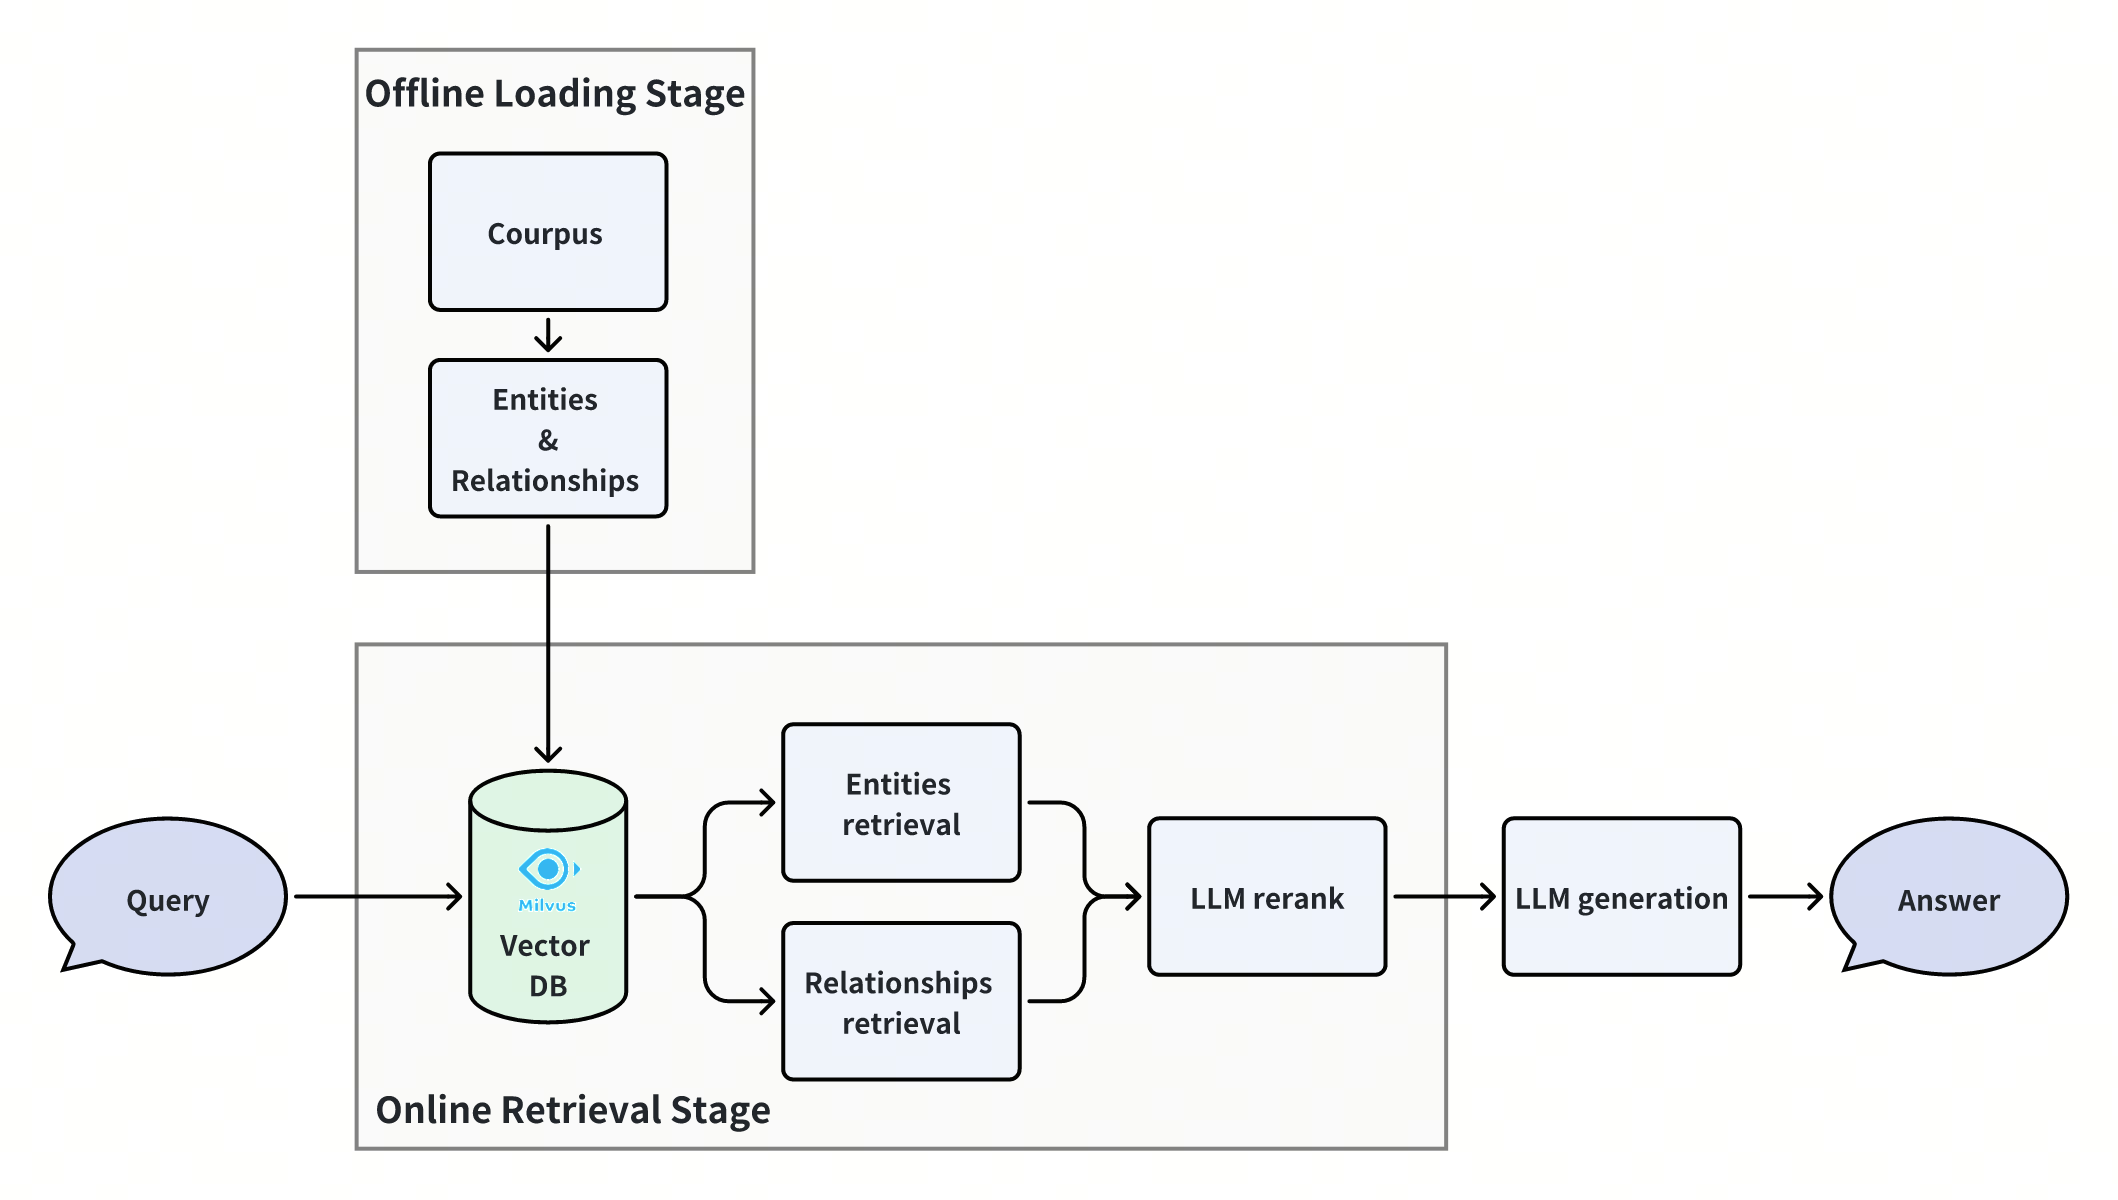
Prasyarat
Sebelum menjalankan notebook ini, pastikan Anda telah menginstal dependensi berikut:
$ pip install --upgrade --quiet pymilvus numpy scipy langchain langchain-core langchain-openai tqdm
Jika Anda menggunakan Google Colab, untuk mengaktifkan dependensi yang baru saja diinstal, Anda mungkin perlu me-restart runtime (klik menu “Runtime” di bagian atas layar, lalu pilih “Restart session” dari menu dropdown).
Kita akan menggunakan model dari OpenAI. Anda harus menyiapkan kunci API OPENAI_API_KEY sebagai variabel lingkungan.
import os

os.environ["OPENAI_API_KEY"] = "sk-***********"
Impor pustaka dan dependensi yang diperlukan.
import numpy as np

from collections import defaultdict
from scipy.sparse import csr_matrix
from pymilvus import MilvusClient
from langchain_core.messages import AIMessage, HumanMessage
from langchain_core.prompts import ChatPromptTemplate, HumanMessagePromptTemplate
from langchain_core.output_parsers import StrOutputParser, JsonOutputParser
from langchain_openai import ChatOpenAI, OpenAIEmbeddings
from tqdm import tqdm
Inisialisasi instance klien Milvus, LLM, dan model embedding.
milvus_client = MilvusClient(uri="./milvus.db")

llm = ChatOpenAI(
    model="gpt-4o",
    temperature=0,
)
embedding_model = OpenAIEmbeddings(model="text-embedding-3-small")
Untuk argumen di MilvusClient:
- Menetapkan
urisebagai file lokal, misalnya./milvus.db, adalah metode yang paling praktis, karena secara otomatis memanfaatkan Milvus Lite untuk menyimpan semua data dalam file ini. - Jika Anda memiliki data berskala besar, Anda dapat menyiapkan server Milvus yang lebih berkinerja tinggi di Docker atau Kubernetes. Dalam pengaturan ini, harap gunakan URI server, misalnya
http://localhost:19530, sebagaiuriAnda. - Jika Anda ingin menggunakan Zilliz Cloud, layanan cloud yang dikelola sepenuhnya untuk Milvus, sesuaikan `
uri` dan `token`, yang sesuai dengan Public Endpoint dan API Key di Zilliz Cloud.
Pemuatan Data Offline
Persiapan Data
Kami akan menggunakan dataset nano yang memperkenalkan hubungan antara keluarga Bernoulli dan Euler sebagai contoh. Dataset nano ini berisi 4 paragraf dan sekumpulan triplet yang sesuai, di mana setiap triplet terdiri dari subjek, predikat, dan objek. Dalam praktiknya, Anda dapat menggunakan pendekatan apa pun untuk mengekstrak triplet dari korpus kustom Anda sendiri.
nano_dataset = [
    {
        "passage": "Jakob Bernoulli (1654–1705): Jakob was one of the earliest members of the Bernoulli family to gain prominence in mathematics. He made significant contributions to calculus, particularly in the development of the theory of probability. He is known for the Bernoulli numbers and the Bernoulli theorem, a precursor to the law of large numbers. He was the older brother of Johann Bernoulli, another influential mathematician, and the two had a complex relationship that involved both collaboration and rivalry.",
        "triplets": [
            ["Jakob Bernoulli", "made significant contributions to", "calculus"],
            [
                "Jakob Bernoulli",
                "made significant contributions to",
                "the theory of probability",
            ],
            ["Jakob Bernoulli", "is known for", "the Bernoulli numbers"],
            ["Jakob Bernoulli", "is known for", "the Bernoulli theorem"],
            ["The Bernoulli theorem", "is a precursor to", "the law of large numbers"],
            ["Jakob Bernoulli", "was the older brother of", "Johann Bernoulli"],
        ],
    },
    {
        "passage": "Johann Bernoulli (1667–1748): Johann, Jakob’s younger brother, was also a major figure in the development of calculus. He worked on infinitesimal calculus and was instrumental in spreading the ideas of Leibniz across Europe. Johann also contributed to the calculus of variations and was known for his work on the brachistochrone problem, which is the curve of fastest descent between two points.",
        "triplets": [
            [
                "Johann Bernoulli",
                "was a major figure of",
                "the development of calculus",
            ],
            ["Johann Bernoulli", "was", "Jakob's younger brother"],
            ["Johann Bernoulli", "worked on", "infinitesimal calculus"],
            ["Johann Bernoulli", "was instrumental in spreading", "Leibniz's ideas"],
            ["Johann Bernoulli", "contributed to", "the calculus of variations"],
            ["Johann Bernoulli", "was known for", "the brachistochrone problem"],
        ],
    },
    {
        "passage": "Daniel Bernoulli (1700–1782): The son of Johann Bernoulli, Daniel made major contributions to fluid dynamics, probability, and statistics. He is most famous for Bernoulli’s principle, which describes the behavior of fluid flow and is fundamental to the understanding of aerodynamics.",
        "triplets": [
            ["Daniel Bernoulli", "was the son of", "Johann Bernoulli"],
            ["Daniel Bernoulli", "made major contributions to", "fluid dynamics"],
            ["Daniel Bernoulli", "made major contributions to", "probability"],
            ["Daniel Bernoulli", "made major contributions to", "statistics"],
            ["Daniel Bernoulli", "is most famous for", "Bernoulli’s principle"],
            [
                "Bernoulli’s principle",
                "is fundamental to",
                "the understanding of aerodynamics",
            ],
        ],
    },
    {
        "passage": "Leonhard Euler (1707–1783) was one of the greatest mathematicians of all time, and his relationship with the Bernoulli family was significant. Euler was born in Basel and was a student of Johann Bernoulli, who recognized his exceptional talent and mentored him in mathematics. Johann Bernoulli’s influence on Euler was profound, and Euler later expanded upon many of the ideas and methods he learned from the Bernoullis.",
        "triplets": [
            [
                "Leonhard Euler",
                "had a significant relationship with",
                "the Bernoulli family",
            ],
            ["leonhard Euler", "was born in", "Basel"],
            ["Leonhard Euler", "was a student of", "Johann Bernoulli"],
            ["Johann Bernoulli's influence", "was profound on", "Euler"],
        ],
    },
]
Kami membangun entitas dan relasi sebagai berikut:
- Entitas adalah subjek atau objek dalam triplet, sehingga kami mengekstraknya langsung dari triplet tersebut.
- Di sini kami membangun konsep hubungan dengan menggabungkan subjek, predikat, dan objek secara langsung dengan spasi di antaranya.
Kami juga menyiapkan sebuah kamus (dict) untuk memetakan ID entitas ke ID relasi, serta kamus lain untuk memetakan ID relasi ke ID bagian teks untuk digunakan nanti.
entityid_2_relationids = defaultdict(list)
relationid_2_passageids = defaultdict(list)

entities = []
relations = []
passages = []
for passage_id, dataset_info in enumerate(nano_dataset):
    passage, triplets = dataset_info["passage"], dataset_info["triplets"]
    passages.append(passage)
    for triplet in triplets:
        if triplet[0] not in entities:
            entities.append(triplet[0])
        if triplet[2] not in entities:
            entities.append(triplet[2])
        relation = " ".join(triplet)
        if relation not in relations:
            relations.append(relation)
            entityid_2_relationids[entities.index(triplet[0])].append(
                len(relations) - 1
            )
            entityid_2_relationids[entities.index(triplet[2])].append(
                len(relations) - 1
            )
        relationid_2_passageids[relations.index(relation)].append(passage_id)
Penyisipan Data
Buat koleksi Milvus untuk entitas, relasi, dan bagian teks. Koleksi entitas dan koleksi relasi digunakan sebagai koleksi utama untuk konstruksi graf dalam metode kami, sedangkan koleksi bagian teks digunakan sebagai perbandingan pencarian RAG sederhana atau untuk tujuan tambahan.
embedding_dim = len(embedding_model.embed_query("foo"))


def create_milvus_collection(collection_name: str):
    if milvus_client.has_collection(collection_name=collection_name):
        milvus_client.drop_collection(collection_name=collection_name)
    milvus_client.create_collection(
        collection_name=collection_name,
        dimension=embedding_dim,
        consistency_level="Bounded",  # Supported values are (`"Strong"`, `"Session"`, `"Bounded"`, `"Eventually"`). See https://milvus.io/docs/tune_consistency.md#Consistency-Level for more details.
    )


entity_col_name = "entity_collection"
relation_col_name = "relation_collection"
passage_col_name = "passage_collection"
create_milvus_collection(entity_col_name)
create_milvus_collection(relation_col_name)
create_milvus_collection(passage_col_name)
Masukkan data beserta informasi metadatanya ke dalam koleksi Milvus, termasuk koleksi entitas, relasi, dan bagian teks. Informasi metadata tersebut mencakup ID bagian teks serta ID entitas atau relasi yang berdekatan.
def milvus_insert(
    collection_name: str,
    text_list: list[str],
):
    batch_size = 512
    for row_id in tqdm(range(0, len(text_list), batch_size), desc="Inserting"):
        batch_texts = text_list[row_id : row_id + batch_size]
        batch_embeddings = embedding_model.embed_documents(batch_texts)

        batch_ids = [row_id + j for j in range(len(batch_texts))]
        batch_data = [
            {
                "id": id_,
                "text": text,
                "vector": vector,
            }
            for id_, text, vector in zip(batch_ids, batch_texts, batch_embeddings)
        ]
        milvus_client.insert(
            collection_name=collection_name,
            data=batch_data,
        )


milvus_insert(
    collection_name=relation_col_name,
    text_list=relations,
)

milvus_insert(
    collection_name=entity_col_name,
    text_list=entities,
)

milvus_insert(
    collection_name=passage_col_name,
    text_list=passages,
)
Inserting: 100%|███████████████████████████████████| 1/1 [00:00<00:00,  1.02it/s]
Inserting: 100%|███████████████████████████████████| 1/1 [00:00<00:00,  1.39it/s]
Inserting: 100%|███████████████████████████████████| 1/1 [00:00<00:00,  2.28it/s]
Pencarian Online
Pencarian Kesamaan
Kami mengambil entitas dan relasi serupa teratas (topK) berdasarkan kueri masukan dari Milvus.
Saat melakukan pencarian entitas, kita harus terlebih dahulu mengekstrak entitas kueri dari teks kueri menggunakan metode tertentu seperti NER (Named-entity recognition). Untuk kesederhanaan, kami menyiapkan hasil NER di sini. Jika Anda ingin mengubah kueri menjadi pertanyaan kustom Anda sendiri, Anda harus mengubah daftar NER kueri yang sesuai. Dalam praktiknya, Anda dapat menggunakan model atau pendekatan lain apa pun untuk mengekstrak entitas dari kueri.
query = "What contribution did the son of Euler's teacher make?"

query_ner_list = ["Euler"]
# query_ner_list = ner(query) # In practice, replace it with your custom NER approach

query_ner_embeddings = [
    embedding_model.embed_query(query_ner) for query_ner in query_ner_list
]

top_k = 3

entity_search_res = milvus_client.search(
    collection_name=entity_col_name,
    data=query_ner_embeddings,
    limit=top_k,
    output_fields=["id"],
)

query_embedding = embedding_model.embed_query(query)

relation_search_res = milvus_client.search(
    collection_name=relation_col_name,
    data=[query_embedding],
    limit=top_k,
    output_fields=["id"],
)[0]
Perluasan Subgraf
Kami menggunakan entitas dan hubungan yang telah diambil untuk memperluas subgraf dan memperoleh hubungan kandidat, kemudian menggabungkannya dari kedua cara tersebut. Berikut adalah diagram alur proses perluasan subgraf:
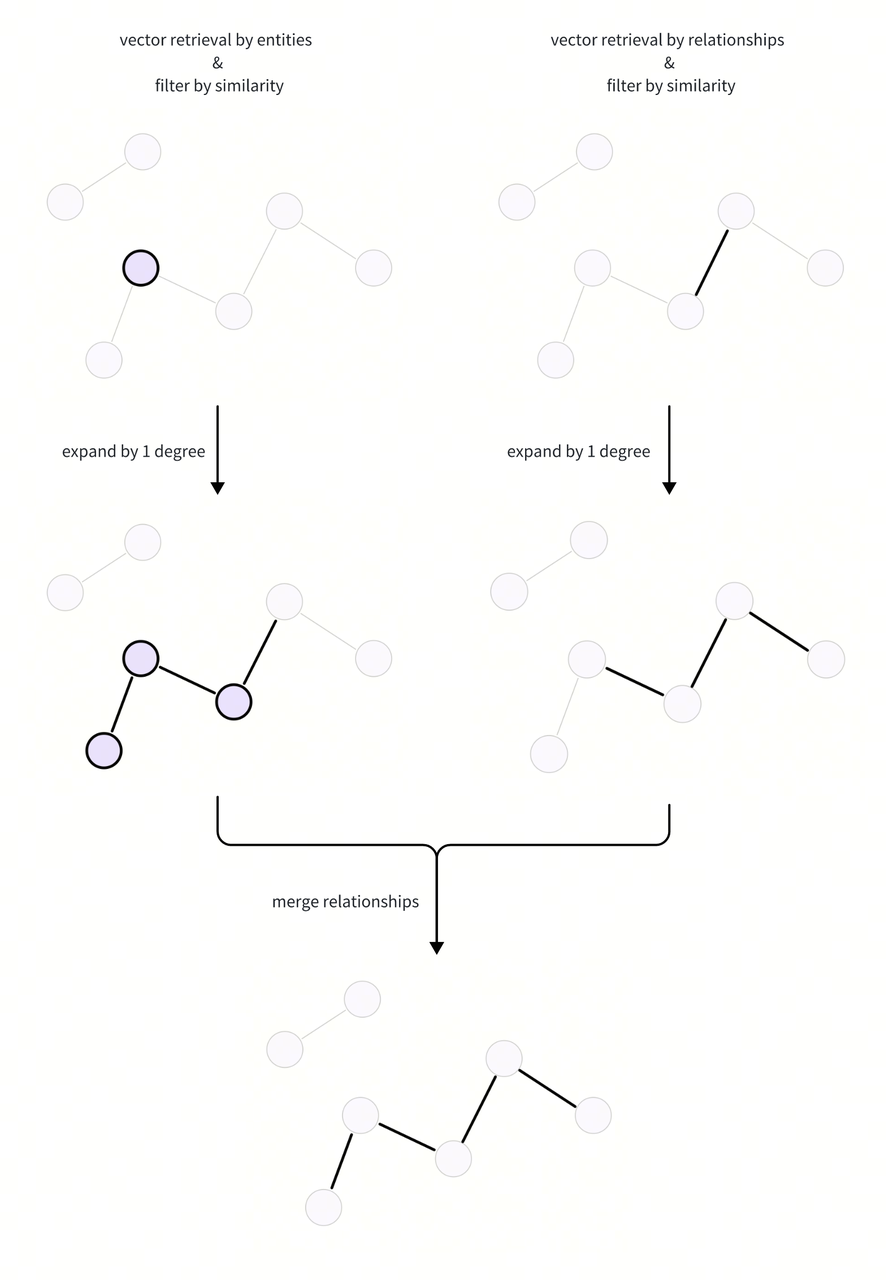
Di sini kami membangun matriks adjacency dan menggunakan perkalian matriks untuk menghitung informasi pemetaan adjacency dalam beberapa derajat. Dengan cara ini, kami dapat dengan cepat memperoleh informasi tentang derajat perluasan apa pun.
# Construct the adjacency matrix of entities and relations where the value of the adjacency matrix is 1 if an entity is related to a relation, otherwise 0.
entity_relation_adj = np.zeros((len(entities), len(relations)))
for entity_id, entity in enumerate(entities):
    entity_relation_adj[entity_id, entityid_2_relationids[entity_id]] = 1

# Convert the adjacency matrix to a sparse matrix for efficient computation.
entity_relation_adj = csr_matrix(entity_relation_adj)

# Use the entity-relation adjacency matrix to construct 1 degree entity-entity and relation-relation adjacency matrices.
entity_adj_1_degree = entity_relation_adj @ entity_relation_adj.T
relation_adj_1_degree = entity_relation_adj.T @ entity_relation_adj

# Specify the target degree of the subgraph to be expanded.
# 1 or 2 is enough for most cases.
target_degree = 1

# Compute the target degree adjacency matrices using matrix multiplication.
entity_adj_target_degree = entity_adj_1_degree
for _ in range(target_degree - 1):
    entity_adj_target_degree = entity_adj_target_degree * entity_adj_1_degree
relation_adj_target_degree = relation_adj_1_degree
for _ in range(target_degree - 1):
    relation_adj_target_degree = relation_adj_target_degree * relation_adj_1_degree

entity_relation_adj_target_degree = entity_adj_target_degree @ entity_relation_adj
Dengan mengambil nilai dari matriks perluasan derajat target, kami dapat dengan mudah memperluas derajat yang sesuai dari entitas dan relasi yang diperoleh untuk mendapatkan semua relasi dari subgraf.
expanded_relations_from_relation = set()
expanded_relations_from_entity = set()
# You can set the similarity threshold here to guarantee the quality of the retrieved ones.
# entity_sim_filter_thresh = ...
# relation_sim_filter_thresh = ...

filtered_hit_relation_ids = [
    relation_res["entity"]["id"]
    for relation_res in relation_search_res
    # if relation_res['distance'] > relation_sim_filter_thresh
]
for hit_relation_id in filtered_hit_relation_ids:
    expanded_relations_from_relation.update(
        relation_adj_target_degree[hit_relation_id].nonzero()[1].tolist()
    )

filtered_hit_entity_ids = [
    one_entity_res["entity"]["id"]
    for one_entity_search_res in entity_search_res
    for one_entity_res in one_entity_search_res
    # if one_entity_res['distance'] > entity_sim_filter_thresh
]

for filtered_hit_entity_id in filtered_hit_entity_ids:
    expanded_relations_from_entity.update(
        entity_relation_adj_target_degree[filtered_hit_entity_id].nonzero()[1].tolist()
    )

# Merge the expanded relations from the relation and entity retrieval ways.
relation_candidate_ids = list(
    expanded_relations_from_relation | expanded_relations_from_entity
)

relation_candidate_texts = [
    relations[relation_id] for relation_id in relation_candidate_ids
]
Kami telah memperoleh hubungan kandidat dengan memperluas subgraf, yang akan diurutkan ulang oleh LLM pada langkah berikutnya.
Penilaian Ulang LLM
Pada tahap ini, kami menerapkan mekanisme self-attention LLM yang kuat untuk menyaring dan menyempurnakan himpunan kandidat hubungan lebih lanjut. Kami menggunakan prompt satu kali (one-shot prompt), yang menggabungkan kueri dan himpunan kandidat hubungan ke dalam prompt, serta menginstruksikan LLM untuk memilih hubungan potensial yang dapat membantu menjawab kueri tersebut. Mengingat beberapa kueri mungkin bersifat kompleks, kami mengadopsi pendekatan Chain-of-Thought, yang memungkinkan LLM mengartikulasikan proses pemikirannya dalam responsnya. Kami menetapkan bahwa respons LLM harus dalam format json agar mudah diparsing.
query_prompt_one_shot_input = """I will provide you with a list of relationship descriptions. Your task is to select 3 relationships that may be useful to answer the given question. Please return a JSON object containing your thought process and a list of the selected relationships in order of their relevance.

Question:
When was the mother of the leader of the Third Crusade born?

Relationship descriptions:
[1] Eleanor was born in 1122.
[2] Eleanor married King Louis VII of France.
[3] Eleanor was the Duchess of Aquitaine.
[4] Eleanor participated in the Second Crusade.
[5] Eleanor had eight children.
[6] Eleanor was married to Henry II of England.
[7] Eleanor was the mother of Richard the Lionheart.
[8] Richard the Lionheart was the King of England.
[9] Henry II was the father of Richard the Lionheart.
[10] Henry II was the King of England.
[11] Richard the Lionheart led the Third Crusade.

"""
query_prompt_one_shot_output = """{"thought_process": "To answer the question about the birth of the mother of the leader of the Third Crusade, I first need to identify who led the Third Crusade and then determine who his mother was. After identifying his mother, I can look for the relationship that mentions her birth.", "useful_relationships": ["[11] Richard the Lionheart led the Third Crusade", "[7] Eleanor was the mother of Richard the Lionheart", "[1] Eleanor was born in 1122"]}"""

query_prompt_template = """Question:
{question}

Relationship descriptions:
{relation_des_str}

"""


def rerank_relations(
    query: str, relation_candidate_texts: list[str], relation_candidate_ids: list[str]
) -> list[int]:
    relation_des_str = "\n".join(
        map(
            lambda item: f"[{item[0]}] {item[1]}",
            zip(relation_candidate_ids, relation_candidate_texts),
        )
    ).strip()
    rerank_prompts = ChatPromptTemplate.from_messages(
        [
            HumanMessage(query_prompt_one_shot_input),
            AIMessage(query_prompt_one_shot_output),
            HumanMessagePromptTemplate.from_template(query_prompt_template),
        ]
    )
    rerank_chain = (
        rerank_prompts
        | llm.bind(response_format={"type": "json_object"})
        | JsonOutputParser()
    )
    rerank_res = rerank_chain.invoke(
        {"question": query, "relation_des_str": relation_des_str}
    )
    rerank_relation_ids = []
    rerank_relation_lines = rerank_res["useful_relationships"]
    id_2_lines = {}
    for line in rerank_relation_lines:
        id_ = int(line[line.find("[") + 1 : line.find("]")])
        id_2_lines[id_] = line.strip()
        rerank_relation_ids.append(id_)
    return rerank_relation_ids


rerank_relation_ids = rerank_relations(
    query,
    relation_candidate_texts=relation_candidate_texts,
    relation_candidate_ids=relation_candidate_ids,
)
Mendapatkan Hasil Akhir
Kami dapat memperoleh bagian teks akhir yang diambil dari hubungan yang telah diurutkan ulang.
final_top_k = 2

final_passages = []
final_passage_ids = []
for relation_id in rerank_relation_ids:
    for passage_id in relationid_2_passageids[relation_id]:
        if passage_id not in final_passage_ids:
            final_passage_ids.append(passage_id)
            final_passages.append(passages[passage_id])
passages_from_our_method = final_passages[:final_top_k]
Kami dapat membandingkan hasilnya dengan metode RAG naif, yang mengambil K paragraf teratas berdasarkan embedding kueri langsung dari kumpulan paragraf.
naive_passage_res = milvus_client.search(
    collection_name=passage_col_name,
    data=[query_embedding],
    limit=final_top_k,
    output_fields=["text"],
)[0]
passages_from_naive_rag = [res["entity"]["text"] for res in naive_passage_res]

print(
    f"Passages retrieved from naive RAG: \n{passages_from_naive_rag}\n\n"
    f"Passages retrieved from our method: \n{passages_from_our_method}\n\n"
)


prompt = ChatPromptTemplate.from_messages(
    [
        (
            "human",
            """Use the following pieces of retrieved context to answer the question. If there is not enough information in the retrieved context to answer the question, just say that you don't know.
Question: {question}
Context: {context}
Answer:""",
        )
    ]
)

rag_chain = prompt | llm | StrOutputParser()

answer_from_naive_rag = rag_chain.invoke(
    {"question": query, "context": "\n".join(passages_from_naive_rag)}
)
answer_from_our_method = rag_chain.invoke(
    {"question": query, "context": "\n".join(passages_from_our_method)}
)

print(
    f"Answer from naive RAG: {answer_from_naive_rag}\n\nAnswer from our method: {answer_from_our_method}"
)
Passages retrieved from naive RAG:
['Leonhard Euler (1707–1783) was one of the greatest mathematicians of all time, and his relationship with the Bernoulli family was significant. Euler was born in Basel and was a student of Johann Bernoulli, who recognized his exceptional talent and mentored him in mathematics. Johann Bernoulli’s influence on Euler was profound, and Euler later expanded upon many of the ideas and methods he learned from the Bernoullis.', 'Johann Bernoulli (1667–1748): Johann, Jakob’s younger brother, was also a major figure in the development of calculus. He worked on infinitesimal calculus and was instrumental in spreading the ideas of Leibniz across Europe. Johann also contributed to the calculus of variations and was known for his work on the brachistochrone problem, which is the curve of fastest descent between two points.']

Passages retrieved from our method:
['Leonhard Euler (1707–1783) was one of the greatest mathematicians of all time, and his relationship with the Bernoulli family was significant. Euler was born in Basel and was a student of Johann Bernoulli, who recognized his exceptional talent and mentored him in mathematics. Johann Bernoulli’s influence on Euler was profound, and Euler later expanded upon many of the ideas and methods he learned from the Bernoullis.', 'Daniel Bernoulli (1700–1782): The son of Johann Bernoulli, Daniel made major contributions to fluid dynamics, probability, and statistics. He is most famous for Bernoulli’s principle, which describes the behavior of fluid flow and is fundamental to the understanding of aerodynamics.']


Answer from naive RAG: I don't know. The retrieved context does not provide information about the contributions made by the son of Euler's teacher.

Answer from our method: The son of Euler's teacher, Daniel Bernoulli, made major contributions to fluid dynamics, probability, and statistics. He is most famous for Bernoulli’s principle, which describes the behavior of fluid flow and is fundamental to the understanding of aerodynamics.
Seperti yang dapat kita lihat, kutipan yang diambil dari metode RAG naif melewatkan satu kutipan yang benar, yang mengakibatkan jawaban yang salah. Kutipan yang diambil dari metode kami benar, dan hal ini membantu mendapatkan jawaban yang akurat untuk pertanyaan tersebut.
