

Vector search is a way of finding information by similarity instead of exact keywords. Content such as text, images, or audio is converted into numeric vectors (embeddings) by a machine-learning model, the query is converted the same way, and the search returns the stored vectors closest to the query vector under a similarity metric like cosine similarity or Euclidean distance. Because nearby vectors tend to have related meaning, vector search can match “laptop won’t turn on” with an article titled "Troubleshooting a notebook that fails to boot", even though they share almost no words.
In production, vector search almost always uses an approximate nearest-neighbor (ANN) index, which skips most of the data and still returns the true nearest neighbors most of the time, in milliseconds over millions or billions of vectors.
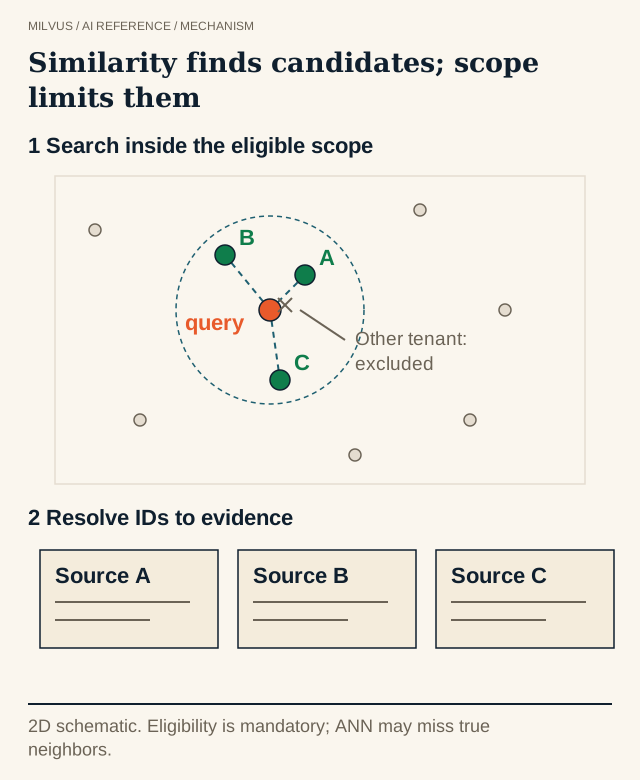 From question to verifiable evidence
How does vector search work?
A vector search system has two phases: indexing, which happens ahead of time, and querying, which happens per request.
Indexing
- Split the content into searchable units. Long documents are chunked into passages; images, products, or user profiles are usually one unit each.
- Embed each unit. An embedding model maps each unit to a fixed-length vector. Dense text models typically output a few hundred to a few thousand dimensions.
- Store vectors with IDs and metadata such as source URL, language, tenant, or date, so results can be filtered and traced back to their origin.
- Build an ANN index over the vectors so queries do not need to compare against everything.
Querying
- Embed the query with the same model (or the query side of a paired model). Vectors from different models live in different spaces and cannot be compared.
- Apply eligibility constraints, such as
tenant == 'acme'oryear >= 2024. - Find the k nearest vectors using the index and the configured metric.
- Fetch the source records, optionally rerank them with a cross-encoder, and show them to the user or pass them to a language model.
Vector search vs. keyword search
| Keyword (lexical) search | Vector (semantic) search | |
|---|---|---|
| Matches on | Shared terms, scored by TF-IDF or BM25 | Closeness of embeddings in vector space |
| Handles synonyms and paraphrase | Poorly, unless you maintain synonym lists | Well, if the model learned the relationship |
| Exact identifiers, SKUs, rare names | Very good | Often weak; rare tokens get blurred |
| Works across languages and modalities | No | Yes, with multilingual or multimodal models |
| Explainability | High: you can see which terms matched | Lower: similarity is a learned geometry |
| Data structure | Inverted index | ANN index (HNSW, IVF, DiskANN, …) |
The two are complementary, which is why many systems run hybrid search: a dense vector search and a BM25 or learned sparse search in parallel, with results fused by reciprocal rank fusion (RRF) or weighted scoring. See How does semantic search differ from keyword search? and What is hybrid search?
How is similarity measured?
The metric defines what “closest” means, and it should match how the embedding model was trained:
| Metric | What it compares | Higher or lower is better |
|---|---|---|
| Cosine similarity | Angle between vectors, ignoring length | Higher |
| Inner product (dot product) | Angle and magnitude together | Higher |
| Euclidean (L2) distance | Straight-line distance between points | Lower |
For unit-length (normalized) vectors all three produce the same ranking, which is why many text models recommend normalizing and using cosine or inner product. The details, with a worked example where they disagree, are in How do cosine similarity, inner product, and L2 differ?
Exact (kNN) vs. approximate (ANN) search
Exact k-nearest-neighbor search compares the query with every candidate vector and returns the true top-k. It is simple and perfectly accurate, but the cost grows linearly with the data: a billion 768-dimensional vectors means hundreds of billions of multiply-adds per query. Exact search is still useful for small collections, for highly selective filters that leave only a few thousand candidates, and as the ground truth when evaluating an index. See Why use a FLAT baseline?
Approximate nearest-neighbor search trades a little accuracy for orders of magnitude more speed. Its quality is measured as recall@k: the fraction of the true top-k neighbors the index actually returns. A well-tuned index commonly reaches 95% to 99% recall at a small fraction of the cost of a full scan. The main families are:
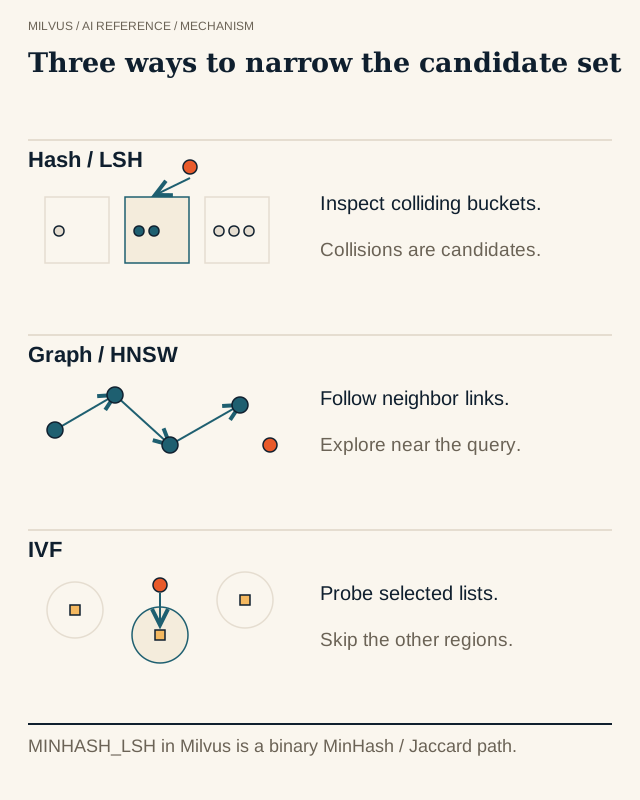 Families of approximate nearest-neighbor indexes
- Graph-based (HNSW): a layered proximity graph that search walks greedily toward the query. Fast and accurate, memory hungry. What is HNSW?
- Cluster-based (IVF): vectors grouped around centroids; the query probes only the nearest
nprobeclusters. How do IVF indexes work? - Quantization (SQ, PQ, RaBitQ): compressed vectors that cut memory and speed up distance math. What is vector quantization?
- Disk-based (DiskANN): a graph stored on SSD for datasets larger than memory. When should you use DISKANN?
Every ANN index exposes a search-time knob that trades recall for latency, such as ef for HNSW or nprobe for IVF. Tune it against measured recall, not intuition. For a deeper treatment, read What is approximate nearest-neighbor search?
Dense and sparse vector search
Most discussions of vector search mean dense vectors, where every dimension carries a learned value. Sparse vectors have a value for only a few dimensions out of a very large vocabulary, as with BM25 term weights or learned sparse models like SPLADE. Sparse vectors are searched with an inverted index and are good at exact-term matching; dense vectors are better at paraphrase. See What are dense and sparse embeddings?
Where is vector search used?
- Semantic search over documentation, tickets, legal or medical text, and source code.
- Retrieval-augmented generation (RAG): fetch the passages a language model should cite. What is RAG?
- Recommendations: retrieve items whose embeddings sit near a user or session embedding.
- Image, video, and audio search, including text-to-image search with multimodal models.
- Deduplication, clustering, and anomaly detection, where “near” means “the same thing” or "nothing like it".
- Agent memory and tool selection, recalling past interactions or picking relevant tools by description.
What are the limitations?
Vector search returns the nearest vectors, not necessarily relevant ones. If you ask for top_k=5, you get five results even when none answers the question, so production systems add a score threshold, a reranker, or a “no good answer” policy. Quality is capped by the embedding model: an off-the-shelf model may not know your product names or domain jargon, and exact identifiers often need keyword or hybrid search. Changing models means re-embedding the corpus, because old and new vectors are not comparable. Filters interact with ANN indexes in non-obvious ways, especially very selective ones. And memory adds up quickly: 100 million 768-dimensional float32 vectors take roughly 300 GB before index overhead, which is why quantization and disk-based indexes matter at scale.
How do you run vector search in Milvus?
Milvus is an open-source vector database that runs the full pipeline above. With PyMilvus, a filtered top-k search on a collection looks like this:
from pymilvus import MilvusClient

client = MilvusClient("milvus_demo.db")   # or a Milvus server / Zilliz Cloud URI

results = client.search(
    collection_name="docs",
    data=[query_vector],                   # embed the query with the same model as the documents
    filter="lang == 'en' and year >= 2024",
    limit=5,
    search_params={"params": {"ef": 64}},  # HNSW: larger ef = higher recall, more latency
    output_fields=["title", "url"],
)
Beyond basic top-k search, Milvus supports:
- Filtered search that restricts the candidate set with boolean expressions over scalar fields before the ANN step. How do metadata filters interact with vector search?
- Range search, which returns everything within a similarity band using
radiusandrange_filterinstead of a fixed k. When should you use range search? - Hybrid search with
hybrid_search(), oneAnnSearchRequestper vector field, and anRRFRankerorWeightedRankerto fuse results. - Full-text search with a built-in BM25 function that turns a
VARCHARfield into aSPARSE_FLOAT_VECTOR, so keyword and semantic search live in one collection. - Metrics
COSINE,IP, andL2for float vectors (L2 is returned as the squared distance),HAMMINGandJACCARDfor binary vectors, andIPorBM25for sparse vectors. - Indexes including FLAT, IVF_FLAT, IVF_PQ, IVF_RABITQ, HNSW, DISKANN, SCANN, and GPU_CAGRA, chosen per field. How do you choose a vector index?
How do you check that vector search is working?
Start with a small corpus and 20 to 50 real queries whose correct answers you know. Run them with a FLAT index to see what the embedding model alone achieves, then switch to your ANN index and measure recall against that baseline. This separates two very different problems: a model that does not understand your data, and an index that is tuned too aggressively. Only then adjust the model, chunking, filters, or index parameters. How do you evaluate retrieval quality? covers the metrics.
Next steps
Run your first search in minutes with the Milvus Quickstart, then explore complete semantic search, RAG, and image search examples in the Milvus Bootcamp. If you would rather not operate the infrastructure, Zilliz Cloud runs managed Milvus.
Related reading
- What is a vector database, and when do you need one?
- What are embeddings in vector search?
- What is full-text search, and how does BM25 fit?
- What is reranking, and when should you apply it?



