

Multi-tenancy in a vector database means serving many customers, teams, or applications from shared infrastructure while keeping each tenant’s data, performance, and lifecycle separate. The core design choice is where to draw the tenant boundary. Milvus supports four levels: one database per tenant, one collection per tenant, one partition per tenant, or a partition key field that maps many tenants into a shared collection. Moving down that list lets you host far more tenants at lower cost, while moving up gives you stronger isolation, per-tenant schemas, and native access control.
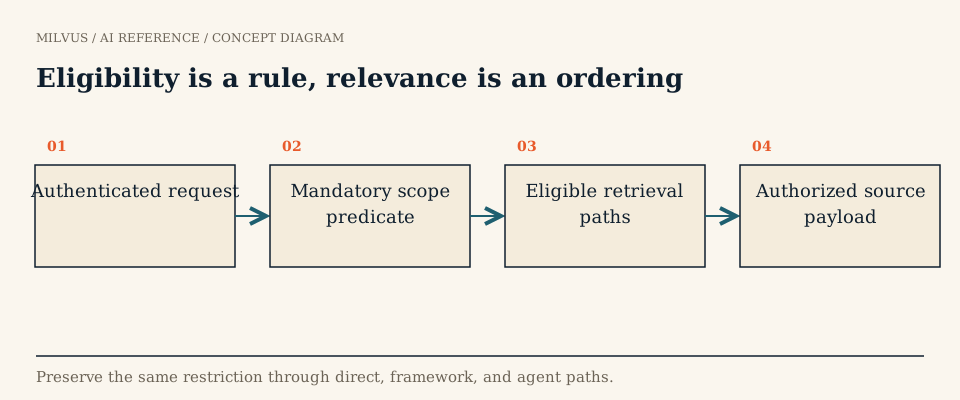 Eligibility is a rule, relevance is an ordering
What are the multi-tenancy strategies in Milvus?
The Milvus docs compare the four strategies along the dimensions that usually decide the question:
| Database per tenant | Collection per tenant | Partition per tenant | Partition key | |
|---|---|---|---|---|
| Default tenant ceiling | 64 databases (maxDatabaseNum) | 65,536 collections (maxCollectionNum) | 1,024 partitions per collection | Millions of tenants |
| Data isolation | Physical | Physical | Physical | Physical + logical (tenants share partitions) |
| Native RBAC per tenant | Yes | Yes | No | No |
| Schema per tenant | Fully independent | Independent | Shared | Shared |
| Search performance | Strong | Strong | Medium | Medium |
| Hot/cold tenant handling | Supported | Supported | Supported | Not currently supported |
| Cross-tenant search | No | No | Yes | Yes |
The ceilings for databases and collections are defaults you can raise, but each collection carries metadata, load state, and memory overhead, so a cluster with tens of thousands of small collections behaves differently from one with a few large ones.
How do you choose between them?
Work through three questions in order.
1. Is this a hard compliance boundary? If tenants are separate enterprise customers with contractual or regulatory isolation, need different schemas or embedding models, or must be restorable and deletable on their own, use database- or collection-per-tenant. You get native RBAC, independent indexes, and simple per-tenant export and drop. If the requirement is truly “separate infrastructure,” a dedicated cluster, or a BYOC deployment, is the next step up.
2. How many tenants, and how skewed? For thousands to millions of users of one SaaS product (per-user notes, per-workspace documents, agent memories), partition key is usually the right default. Declare a scalar field with is_partition_key=True; Milvus hashes tenant values into a fixed set of partitions (16 by default, configurable with num_partitions) and prunes the search to the matching partition when you filter on the key.
3. Do a few tenants dominate? Real tenant distributions are skewed: a handful of tenants often hold most of the data and traffic. A hybrid works well here: put the large tenants in their own collections and the long tail in a shared partition-key collection, with a routing table in your application that knows which is which.
Partition-per-tenant sits in the middle. It gives physical separation and the ability to load and release individual tenants, but the 1,024-per-collection limit caps it, and partition key has largely replaced it for large tenant counts.
How does partition key search work in practice?
schema.add_field("tenant_id", DataType.VARCHAR, max_length=64, is_partition_key=True)

client.search(
    collection_name="docs",
    data=[query_vector],
    filter='tenant_id == "acme" && doc_type == "policy"',
    limit=10,
)
The filter on tenant_id is what makes the search both correct and fast. The key value cannot be empty or null, so every record has a tenant. You can also filter on several tenants with tenant_id in ["a", "b"] when cross-tenant search is a feature.
For large shared collections, partition key isolation goes further. Setting the collection property partitionkey.isolation to true at creation makes Milvus build a separate index per partition key value, so a tenant’s search never walks other tenants’ graph neighborhoods. It currently applies to HNSW indexes, and each search filter must target exactly one partition key value. Research on multi-tenant ANN indexing, such as Curator, frames the same trade-off: a shared index saves memory but slows selective tenant queries, while per-tenant indexes are fast but memory-hungry.
Isolation is a security property, not just a layout
With database- and collection-level tenancy, you can grant each tenant’s service identity access to only its own resources using Milvus RBAC. With partitions and partition keys, RBAC cannot separate tenants inside the collection, so the tenant filter is the security boundary, and your application must own it:
- Take the tenant ID from the authenticated session on the server, never from request parameters or an LLM’s tool arguments.
- Apply it in one shared retrieval function used by every path: direct search, framework retrievers, agent and MCP tools, fetch-by-ID, and reranking.
- Fail closed when the tenant value is missing.
How do you handle noisy neighbors?
Data isolation does not stop one tenant’s heavy ingest or query burst from raising everyone’s latency. Milvus gives you several levers:
- Resource groups pin a collection’s replicas to a dedicated set of query nodes, so a premium tenant’s collection can be physically separated from shared workloads. Pass
resource_groups(andreplica_number) when loading. - Load and release for database, collection, and partition tenancy keeps only active tenants in memory, which is the “hot/cold” support in the table above.
- Quotas and rate limits at the Milvus and application layers cap what any one caller can push.
Test with a realistic mix: large, small, idle, and bursty tenants, measuring p99 latency for small tenants while a large one is bulk-loading. That is where most multi-tenant designs show their weakness. Metadata filter performance and overall scalability both feed into those numbers.
Plan the tenant lifecycle
Design for onboarding, schema evolution, export, and deletion from the start. Dropping a collection or database removes a tenant cleanly. In a partition-key collection, removing a tenant is a delete by filter (tenant_id == "acme") followed by compaction, and a full export is a filtered query. Write these flows down and test them, because “delete all of this customer’s data within 30 days” is a request every B2B product eventually gets.
Next steps
Read the Milvus multi-tenancy guide and partition key guide before choosing, then build a two-tenant test with similar documents and verify no path leaks across. For regulated workloads, see how healthcare evidence retrieval handles isolation. If you would rather not operate tenant isolation yourself, Zilliz Cloud offers managed Milvus, and cost comparisons for managed and self-hosted vector search help size the decision.



