

FAISS (Facebook AI Similarity Search) is an open-source C++ library from Meta, with Python bindings, for similarity search and clustering of dense vectors. It is not a single algorithm and not a database. It is a toolkit that implements most of the standard vector index structures (exact flat search, IVF, HNSW, product and scalar quantization, and combinations of them) on CPU and GPU. You give it arrays of vectors, and it returns the IDs and distances of the nearest ones.
Because FAISS is so widely used, its index names and its “index factory” notation have become a common vocabulary for talking about vector indexes. Milvus builds on several of the same ideas through its Knowhere engine, and Milvus 3.0 adds a FAISS index type that accepts FAISS factory strings directly.
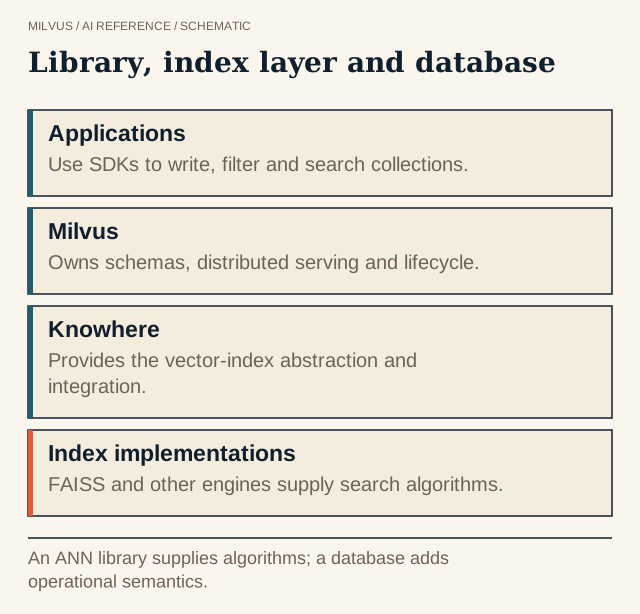 Library, index layer and database. An ANN library supplies algorithms; a database adds operational semantics.
What problem does FAISS solve?
Given a collection of N vectors and a query, the exact answer to “which k vectors are closest?” requires N distance computations. That is fine for thousands of vectors and too slow for hundreds of millions. FAISS provides data structures that trade a little accuracy for much less work, along with highly optimized code for the distance math itself (SIMD on CPU, CUDA on GPU). It supports L2 distance and inner product as its core metrics; cosine similarity is inner product on normalized vectors.
The library was released in 2017 by Facebook AI Research, and its design is described in The Faiss library (Douze et al., 2024).
How does FAISS work?
Almost every FAISS index answers two questions:
- Which vectors should be compared at all? This is the non-exhaustive part. Flat indexes compare everything. IVF indexes cluster the data with k-means and only scan the clusters nearest the query. HNSW indexes walk a neighbor graph.
- How is each vector stored, and how are distances computed? This is the encoding. Flat storage keeps full float32 values. Scalar quantization (
SQ8) stores one byte per dimension. Product quantization (PQ) splits a vector into sub-vectors and stores a short code for each, so distances are estimated with lookup tables.
Optional extras sit around those two choices: vector transforms such as PCA or OPQ before indexing, and a refinement stage that re-scores a shortlist with more precise vectors.
What is the FAISS index factory?
The index factory builds an index from a short, comma-separated string that names these pieces in order. Reading a few strings teaches you most of FAISS:
| Factory string | What it means |
|---|---|
Flat | Exact brute-force search over full vectors |
IVF4096,Flat | 4,096 k-means clusters; full vectors inside each list |
IVF4096,SQ8 | Same clustering; vectors stored as 8-bit scalar codes |
IVF4096,PQ64x8 | Same clustering; each vector stored as 64 PQ codes of 8 bits |
HNSW32,Flat | HNSW graph with 32 links per node; full vectors |
OPQ64,IVF4096,PQ64 | An OPQ rotation, then IVF, then PQ codes |
IVF4096,PQ64,RFlat | IVF-PQ for candidates, then exact re-ranking of the shortlist |
In Python, the same idea looks like this:
import faiss

index = faiss.index_factory(768, "IVF4096,Flat", faiss.METRIC_INNER_PRODUCT)
index.train(train_vectors)   # learns the 4,096 centroids
index.add(vectors)
index.nprobe = 16            # clusters to scan per query
distances, ids = index.search(queries, 10)
This is also why “FAISS vs HNSW” is a category mistake. HNSW is a graph algorithm, and FAISS is one of several libraries that implement it. The useful comparison is between index structures (for example HNSW32,Flat versus IVF4096,PQ64), which are explained on their own pages for HNSW, IVF, and quantization.
What are FAISS’s main index classes?
IndexFlatL2/IndexFlatIP: exact search, the ground truth for measuring recall.IndexIVFFlat,IndexIVFScalarQuantizer,IndexIVFPQ: IVF with full, SQ, or PQ storage. These must be trained before vectors are added, and are tuned at query time withnprobe.IndexHNSWFlat: HNSW graph, tuned withefConstructionat build time andefSearchat query time.IndexPQ,IndexScalarQuantizer: compressed flat scans without partitioning.- Binary indexes (such as
IndexBinaryFlat): Hamming distance over bit vectors. - GPU indexes: GPU versions of flat and IVF indexes, plus NVIDIA’s cuVS-based implementations, for large batches of queries.
FAISS library vs. vector database: what is the difference?
FAISS is an in-process library. It owns the index structure and search math, and leaves everything around them to your application:
| Concern | FAISS (library) | Milvus (vector database) |
|---|---|---|
| Data model | Arrays of vectors with integer IDs | Collections with typed fields: vectors, scalars, JSON, text |
| Persistence | You serialize index files yourself | Durable storage, write-ahead log, automatic index builds |
| Updates and deletes | Depends on index type; often rebuild | Inserts, upserts, and deletes with background compaction |
| Metadata filtering | ID selectors only; you maintain the mapping | Boolean filter expressions on scalar fields during search |
| Scale-out | Single process; sharding is your job | Distributed query nodes, replicas, and shards |
| Hybrid and full-text search | Not included | Dense, sparse, and BM25 search with rerankers |
FAISS is a strong choice for research, offline batch jobs, or a single-process service where the whole index fits on one machine and you control the data lifecycle. When an application needs concurrent writes, filtering, durability, and serving across many nodes, a database such as Milvus handles that surrounding work. For more on that boundary, see what a vector database is.
How does Milvus relate to FAISS?
Milvus performs vector search through Knowhere, its vector execution engine, which integrates several index libraries and exposes them as named Milvus index types: FLAT, IVF_FLAT, IVF_SQ8, IVF_PQ, HNSW and its quantized variants, DISKANN, GPU indexes, and more. Each has a documented parameter contract and works with Milvus features such as filtering and iterators. For most workloads, pick one of these dedicated types.
Milvus 3.0.0 and later also provide an expert-level FAISS index type that passes a FAISS factory string through via faiss_index_name. According to the Milvus FAISS guide, it requires PyMilvus 3.0.0 or later, supports FLOAT_VECTOR (for example Flat, IVF64,Flat, HNSW16,Flat with L2, IP, or COSINE) and BINARY_VECTOR (BFlat with HAMMING), and takes factory-specific search parameters such as nprobe, efSearch, or k_factor:
index_params = client.prepare_index_params()
index_params.add_index(
    field_name="vector",
    index_name="faiss_ivf_flat",
    index_type="FAISS",
    metric_type="L2",
    params={"faiss_index_name": "IVF64,Flat"},
)
client.create_index(collection_name="docs", index_params=index_params)

results = client.search(
    collection_name="docs",
    anns_field="vector",
    data=[query_vector],
    limit=5,
    search_params={"params": {"nprobe": 8}},
)
The passthrough has documented limits. It runs on CPU only; it does not support FLOAT16_VECTOR, BFLOAT16_VECTOR, INT8_VECTOR, or SPARSE_FLOAT_VECTOR; scalar filtering works only when the underlying FAISS index supports an ID selector; search iterators are not supported; and raw vectors cannot be retrieved from the index. Use it when you have a tested FAISS recipe with no dedicated Milvus equivalent, and validate the exact string on your Milvus version first.
Where to go next
If you are moving from a FAISS prototype to a service, map your factory string to the matching Milvus index type (for example IVF4096,Flat to IVF_FLAT with nlist=4096, or HNSW32,Flat to HNSW with M=32), load your vectors with the Milvus Quickstart, and compare recall against your FAISS baseline. The index selection guide helps if you are not sure which structure fits, and the ANN overview explains the families behind them.


