

Reranking is a second retrieval stage that takes the top candidates from a fast first-stage search and reorders them with a more accurate, more expensive relevance model. A typical RAG pipeline retrieves 50 to 200 passages with vector or hybrid search, scores each one against the query with a cross-encoder, and passes only the best 5 to 10 to the language model. The first stage is built for recall at scale; the reranker is built for precision on a short list.
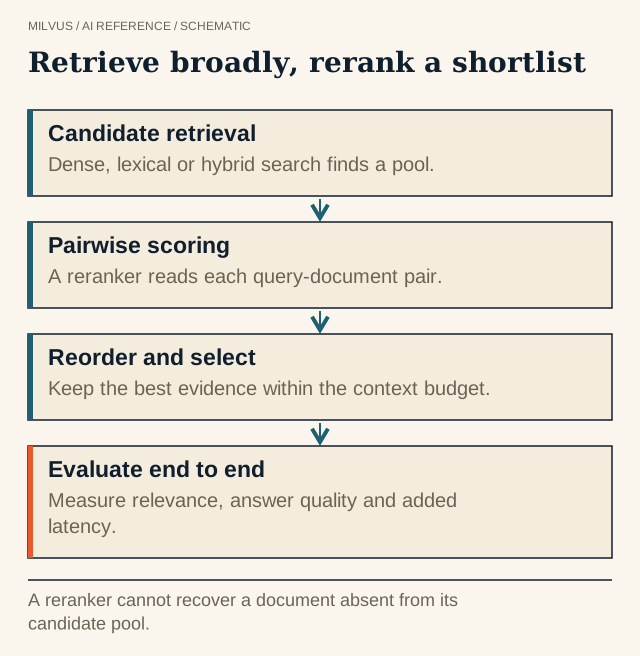 Retrieve broadly, rerank a shortlist. A reranker cannot recover a document absent from its candidate pool.
Why isn’t vector search enough on its own?
Embedding search uses a bi-encoder: the query and each document are encoded separately into one vector, and relevance is a cosine or dot product between them. That separation is what makes it fast. Documents are embedded once, indexed with HNSW or IVF, and searched in milliseconds across millions of records.
The same separation limits accuracy. The model never sees the query and the document together, so it cannot check whether a passage actually answers the question, handles negation, or matches the specific entity asked about. It only knows the two texts land in similar regions of embedding space. Results that are “about the topic” but not useful often end up near the top, and in RAG every irrelevant passage costs context tokens and invites hallucination.
A reranker sees the pair together. Because it only runs on a few dozen to a few hundred candidates, it can afford a model that would be far too slow to run over the whole corpus.
Types of rerankers
The word “reranking” covers several different computations. It helps to keep them apart.
| Type | What it looks at | Output | Typical cost |
|---|---|---|---|
| Cross-encoder | Query and passage concatenated, full attention across both | A relevance score per pair | One transformer pass per candidate |
| Late interaction (ColBERT-style) | Precomputed token vectors for query and passage, compared with MaxSim | A score per pair | Cheaper than cross-encoder, more storage |
| LLM / listwise | Several candidates at once in a prompt | An ordering of the list | Highest latency and cost |
| Rank fusion (RRF, weighted) | Only the scores or ranks from multiple retrievers | A merged list | Negligible |
| Rule-based (decay, boost) | Metadata such as timestamp, distance, popularity | Adjusted scores | Negligible |
Cross-encoders are the classic choice for RAG. Fusion and rule-based rankers do not read content at all; they combine or adjust signals that already exist. A production pipeline often uses more than one: fuse dense and keyword results, then apply a cross-encoder to the fused list. Late interaction is covered in its own article on late-interaction retrieval.
How a retrieve-and-rerank pipeline works
- Retrieve broadly. Run vector search, keyword search, or both, with the same tenant and permission filters, and keep a candidate pool larger than you need, often 50 to 100 per query.
- Fuse if you have multiple paths. Merge dense and sparse results with Reciprocal Rank Fusion or weighted scores.
- Rerank. Score each candidate against the query with the reranking model and sort by that score.
- Truncate. Keep the top few results for the prompt or the results page.
Two rules follow from this structure. First, reranking can only reorder what retrieval found; a relevant document missing from the pool cannot be recovered, so poor candidate recall is a retrieval problem. Second, the pool size is a latency dial. A cross-encoder’s cost grows linearly with candidates, so doubling the pool roughly doubles reranking time.
Reranking in Milvus
Milvus supports reranking directly in a search request through the Function API (Milvus 2.6 and later), using FunctionType.RERANK. You pass the function as ranker to search() or hybrid_search().
Rank fusion for hybrid search. RRF scores each document as the sum of 1 / (k + rank) across result lists. The smoothing parameter k defaults to 60 (range 0 to 16384); larger values flatten the advantage of the top ranks.
from pymilvus import Function, FunctionType

rrf = Function(
    name="rrf",
    input_field_names=[],
    function_type=FunctionType.RERANK,
    params={"reranker": "rrf", "k": 60},
)
The weighted ranker instead combines scores: set "reranker": "weighted", provide one weight in [0, 1] per search path in weights, and optionally set norm_score to normalize raw scores (using arctan) before weighting, which matters when paths use different metrics.
Model rankers for semantic reranking. A model ranker sends the query and a VARCHAR field of each candidate to an external model service and reorders by the returned relevance scores. Supported providers include tei, vllm, Cohere, Voyage AI, SiliconFlow, DashScope, and Hugging Face.
model_ranker = Function(
    name="semantic_ranker",
    input_field_names=["document"],      # one VARCHAR field
    function_type=FunctionType.RERANK,
    params={
        "reranker": "model",
        "provider": "tei",
        "queries": ["how do I rotate API keys?"],
        "endpoint": "http://reranker:8080",
    },
)

results = client.search(
    collection_name="kb",
    data=[query_vector],
    anns_field="embedding",
    limit=10,
    output_fields=["document"],
    ranker=model_ranker,
)
The number of strings in queries must match the number of search queries. Model rankers and decay rankers cannot be combined with grouping search.
Decay and boost rankers. Decay rankers (Gaussian, exponential, linear) blend similarity with a numeric field such as a timestamp or distance, so recent or nearby results rank higher. They read one numeric field and require the field’s units to match the origin, scale, and offset you configure. A boost ranker (Milvus 2.6.2+) applies a filter expression to the candidates and applies a weight to the scores of the matches, which is handy for promoting in-stock products or demoting outdated documents without retraining anything.
Client-side reranking. If you prefer to run models in your application, the PyMilvus model library provides rerank functions such as BGERerankFunction and CrossEncoderRerankFunction that operate on the results Milvus returns.
To choose a specific model, see the reranking model catalog.
When should you apply reranking?
Reranking is usually worth it when:
- The first page of results is “on topic” but often not the right answer.
- You feed retrieved chunks into an LLM and want fewer, better passages in context.
- You run hybrid search and need one consistent ordering of candidates from different retrievers.
- Queries are long, conversational, or involve negation and comparisons that single vectors blur.
It is less useful when the corpus is small enough that exact search already returns precise results, when strict latency budgets cannot absorb a model call per request, or when failures come from missing candidates rather than wrong ordering.
How to evaluate a reranker
Freeze the candidate pool, then compare “no rerank” against each reranker on the same judged queries. Measure NDCG@10 or MRR for ordering, and candidate Recall@k separately so you know whether the first stage is the bottleneck. Record added p50/p99 latency, cost per thousand queries, and timeouts. Include queries with exact identifiers, long documents that may be truncated by the model’s context limit, and queries with no correct answer. Scores from different rerankers are not calibrated probabilities, so revalidate any score threshold when you change models or pool size. The retrieval evaluation guide covers the metrics in detail.
For end-to-end examples, the Milvus Bootcamp includes RAG pipelines with reranking. Related reading: hybrid search and choosing embedding models to evaluate.


