

AI agent memory is the system that lets an LLM agent keep useful information beyond a single context window, such as user preferences, facts learned in past sessions, and what happened in earlier tasks, and bring the right pieces back when they matter. Architecturally it has two halves: a write path that decides what to remember, extracts it, deduplicates it, and stores it with metadata; and a read path that retrieves relevant memories, scoped to the right user, ranked by relevance, recency, and importance. In Milvus, that usually means one collection of memory records with a vector field, a partition key per user or tenant, and scalar fields for type, time, importance, and status.
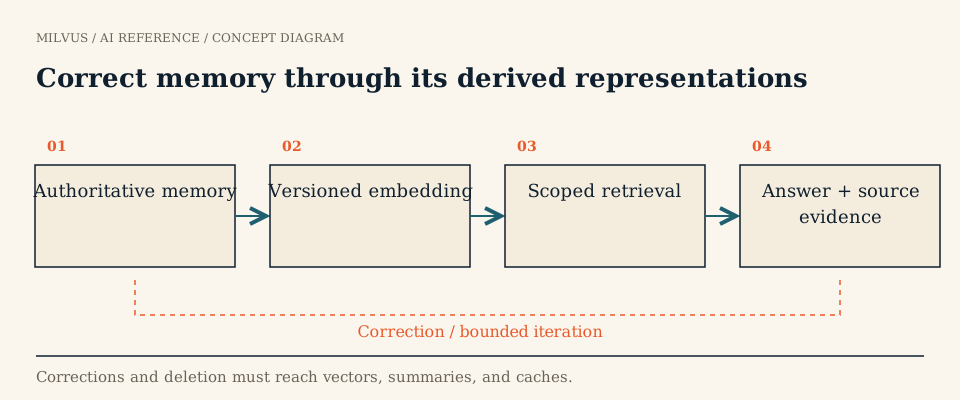 Correct memory through its derived representations
Why do agents need memory beyond the context window?
LLMs are stateless: each call sees only the tokens you send. Long context windows help within a session, but they do not persist across sessions, they get expensive as they grow, and models use information in the middle of very long prompts less reliably. Memory solves a selection problem: out of everything the agent has seen, which few hundred tokens should go into this prompt?
Research systems frame it the same way. The CoALA framework (Sumers et al.) describes language agents with working memory plus long-term episodic, semantic, and procedural stores. MemGPT (Packer et al.) treats the context window like RAM and moves information to and from external storage, as an operating system pages memory. Generative Agents (Park et al.) keeps a “memory stream” of observations and retrieves by a mix of recency, importance, and relevance. The differences between memory types are covered in working, episodic, semantic, and procedural memory; this page focuses on the architecture and the Milvus schema.
Memory vs RAG: what is the difference?
Both retrieve text by similarity, and both can use the same vector database. The difference is where the data comes from and how it changes.
| RAG knowledge base | Agent memory | |
|---|---|---|
| Source | Documents curated by the organization | The agent’s own interactions and observations |
| Scope | Shared by many users | Usually per user, per agent, or per session |
| Writes | Batch ingestion when documents change | Continuous, during or after conversations |
| Updates | Replace a document version | Correct, merge, supersede, decay, and forget individual facts |
| Main risk | Stale or missing documents | Leaking across users, remembering wrong or outdated facts |
What should a memory record contain?
A practical Milvus schema for long-term memory:
| Field | Type | Purpose |
|---|---|---|
memory_id | VARCHAR, primary key | Stable ID for updates, deletes, and citations |
user_id | VARCHAR, partition key | Isolation and fast per-user search |
agent_id, session_id | VARCHAR | Which agent and conversation produced it |
memory_type | VARCHAR | episodic, semantic, procedural, summary |
content | VARCHAR | The memory text that is embedded and shown to the model |
embedding | FLOAT_VECTOR | Similarity search |
importance | FLOAT | 0-1 score assigned at write time |
created_at, last_accessed_at | INT64 (epoch seconds) | Recency scoring and expiry |
status | VARCHAR | active, superseded, deleted |
supersedes | VARCHAR | ID of the memory this one replaces |
source | JSON | Provenance: message IDs, tool call, confidence |
Setting is_partition_key=True on user_id makes Milvus hash users into partitions (16 by default, configurable with num_partitions), and a filter like user_id == "u_42" searches only the relevant partition. For memory-heavy apps with many users and HNSW indexes, the partitionkey.isolation collection property builds the index per partition group so each query touches less data; it requires that every search filters on exactly one partition-key value. For broader multi-tenant trade-offs, see designing multi-tenancy.
from pymilvus import MilvusClient, DataType

client = MilvusClient(uri="http://localhost:19530")
s = client.create_schema(enable_dynamic_field=False)
s.add_field("memory_id", DataType.VARCHAR, is_primary=True, max_length=64)
s.add_field("user_id", DataType.VARCHAR, max_length=64, is_partition_key=True)
s.add_field("memory_type", DataType.VARCHAR, max_length=16)
s.add_field("content", DataType.VARCHAR, max_length=4096)
s.add_field("embedding", DataType.FLOAT_VECTOR, dim=1024)
s.add_field("importance", DataType.FLOAT)
s.add_field("created_at", DataType.INT64)
s.add_field("status", DataType.VARCHAR, max_length=16)
s.add_field("source", DataType.JSON)

idx = client.prepare_index_params()
idx.add_index("embedding", index_type="HNSW", metric_type="COSINE")
client.create_collection("agent_memory", schema=s, index_params=idx)
The write path: what gets remembered?
Storing every message verbatim fills memory with noise. A sturdier write path:
- Extract. After a turn or a session, have an LLM pull out candidate memories: stated preferences (“prefers aisle seats”), facts (“works at Acme, on the payments team”), outcomes (“the CSV import failed because of a BOM”). Keep each memory atomic, one fact per record.
- Score importance. Ask the model or use rules to rate how likely the fact is to matter later (a name or allergy is high, small talk is low).
- Deduplicate and reconcile. Search existing memories for the same user with high similarity. Then decide: add (new fact), update (refines an existing one; use
upserton the samememory_id), supersede (contradicts an older fact; write the new record and mark the old onesuperseded), or ignore (already known). - Store with provenance. Keep the source message IDs, so a summary can be checked or regenerated.
Treat the governed record as the source of truth and the vector index as derived from it. The memsearch project makes this explicit: memories live in Markdown files, and Milvus is a rebuildable search index over them. A transactional database can play the same role.
The read path: how do you retrieve the right memories?
Scope first. Filter by
user_id,status == "active", and any agent or type constraints. These filters come from the authenticated session, never from the model.Retrieve candidates by vector similarity, over-fetching (for example 30-50) so reranking has room. Add hybrid search with BM25 if users refer to names, codes, or other exact terms.
Rescore with a blend of signals. A common form, popularized by Generative Agents, is
score = w_rel · similarity + w_rec · recency + w_imp · importance, withrecency = 0.995 ^ hours_since_last_accessGenerative Agents used equal weights and exponential decay per simulated hour; tune the weights and decay rate on your own tasks. The sketch below measures recency from
created_atfor brevity; uselast_accessed_atif you track it.Budget the context. Take the top 5-15 memories that fit a fixed token budget, group them by type, and label them as memories (not instructions) in the prompt.
Update access stats for the memories actually used.
import time
now = time.time()
hits = client.search(
    "agent_memory", data=[embed(user_msg)], limit=40,
    filter=f'user_id == "{uid}" and status == "active"',
    output_fields=["content", "memory_type", "importance", "created_at"],
)[0]

def score(h):
    e = h["entity"]
    similarity = (h["distance"] + 1) / 2          # COSINE score in [-1, 1] -> [0, 1]
    recency = 0.995 ** ((now - e["created_at"]) / 3600)
    return 1.0 * similarity + 0.5 * recency + 0.5 * e["importance"]

context_memories = sorted(hits, key=score, reverse=True)[:8]
Check the score direction before blending. For COSINE and IP, the returned distance is a similarity where higher means closer, and it can be negative; for L2 it is a true distance where lower means closer. Map it to a non-negative “higher is better” value first (as above for COSINE, or 1 / (1 + d) for L2), otherwise weights and decay factors push results the wrong way. Recency and importance only reorder memories that are still valid: superseded or expired facts are removed by the status == "active" filter, not by a low score.
Corrections, expiry, and deletion
Memory must be able to change. A newer correction should beat an older, more similar memory, which is why status and supersedes exist instead of relying on recency weighting alone. Deletion requests (including privacy erasure) must reach the source record, the Milvus entity, caches, and any summaries built from it. Policies for supersession, TTL, decay, consolidation, and hard deletion are covered in how to correct, expire, and delete agent memory.
How do you evaluate agent memory?
Test behavior over time, not single lookups:
- Recall across sessions: after several sessions, does the agent use a preference stated in the first?
- Updates: after a correction (“I moved to Berlin”), does it stop using the old fact?
- Isolation: can any query surface another user’s memory? This should be impossible by construction.
- Deletion: after "forget my address", is it gone from answers, search, and summaries?
- Noise: does memory retrieval add irrelevant context that degrades answers?
Public long-conversation benchmarks such as LoCoMo and LongMemEval are useful references, but your own scripted multi-session scenarios matter more. Measure memory retrieval latency separately from the agent’s other tool calls.
Getting started
Start narrow: one memory type (say, user preferences) with a clear write rule and a clear way to correct it, then add episodic and procedural memory once that works. The Basic Memory with Milvus tutorial builds a working memory layer with Markdown sources and Milvus search, and the Milvus Quickstart gets a local instance running in minutes. For many users in production, Zilliz Cloud runs the same schema as a managed service.
Related reading
- How do working, episodic, semantic, and procedural agent memory differ?
- How should an agent memory system handle corrections, expiry, and deletion?
- How can vector search retrieve useful agent trajectories?
- When is a semantic cache useful, and how do you prevent stale answers?
- How do LangGraph state and Milvus retrieval work together?
- What does eventual consistency mean for vector search?


