

Graph RAG (also written GraphRAG) is a form of retrieval-augmented generation that retrieves over a knowledge graph of entities and their relationships instead of, or in addition to, a flat list of text chunks. An LLM or extraction pipeline turns documents into nodes (people, products, components, places) and edges ("acquired", "depends on", “taught”), and at query time the system follows those edges to collect connected evidence. That makes it better than plain vector RAG at multi-hop questions and at “what are the main themes across all of this?” questions, at the price of a more expensive and more fragile indexing pipeline.
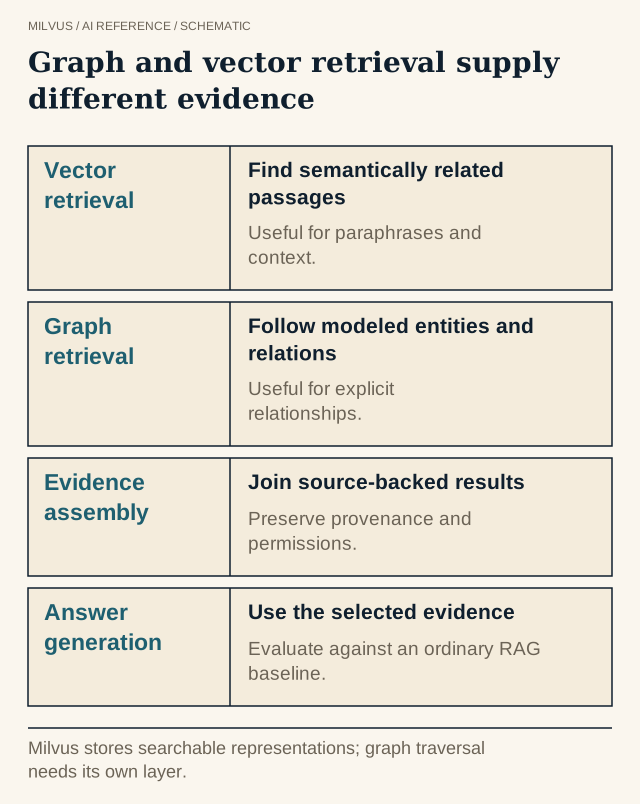 Graph and vector retrieval supply different evidence. Milvus stores searchable representations; graph traversal needs its own layer.
Why does plain vector RAG struggle with some questions?
Standard RAG embeds the question and returns the chunks closest to it. That works when one passage contains the answer. It breaks in two situations:
- Multi-hop questions. “Who is the son of Euler’s teacher?” requires one passage saying Johann Bernoulli taught Euler and another saying Daniel Bernoulli is Johann’s son. The second passage never mentions Euler, so it is not similar to the question and is unlikely to be retrieved.
- Global questions. “What are the main risk themes across these 2,000 incident reports?” has no single relevant chunk. Top-k retrieval returns ten fragments, not an overview.
A graph makes the hidden connection explicit (Euler → taught by → Johann Bernoulli → father of → Daniel Bernoulli), and a graph’s community structure gives a natural way to summarize a corpus.
How does Graph RAG work?
Most implementations share an indexing phase and a query phase.
Indexing
- Split documents into text units, as in ordinary RAG.
- Extract entities and relationships from each unit with an LLM or NER/relation-extraction model, producing triples such as (Daniel Bernoulli, son of, Johann Bernoulli) plus descriptions and source references.
- Resolve entities so "J. Bernoulli", "Johann Bernoulli", and "Bernoulli (the elder)" become one node.
- Build the graph and, in Microsoft’s GraphRAG, cluster it into hierarchical communities with the Leiden algorithm.
- Summarize communities bottom-up with an LLM, so each cluster of related entities has a precomputed report.
- Embed entities, relationships, community reports, and text units so they can be found by similarity.
Querying
- Local search finds the entities most related to the question (usually by vector similarity), expands to their neighbors and relationships, and passes those plus the linked source text to the LLM. Good for specific, multi-hop questions.
- Global search sends the question to many community summaries, has the LLM produce partial answers from each, and reduces them into a final answer (a map-reduce pattern). Good for corpus-wide sensemaking.
- Microsoft’s implementation also offers DRIFT search, which mixes local search with community context, and a basic vector-search mode.
The GraphRAG paper by Edge et al. reported that, on corpora of about one million tokens, the community-summary approach produced substantially more comprehensive and diverse answers than vector RAG for global questions.
Graph RAG vs vector RAG
| Vector RAG | Graph RAG | |
|---|---|---|
| Unit of retrieval | Text chunks | Entities, relations, subgraphs, community summaries (plus chunks) |
| Strongest at | Direct factual lookups, paraphrase matching | Multi-hop reasoning, relationship questions, corpus-level themes |
| Indexing cost | Embedding calls only | Embedding plus LLM extraction and summarization over the whole corpus, often many times more expensive |
| Updating | Re-embed changed chunks | Re-extract, re-resolve entities, possibly re-cluster and re-summarize |
| Explainability | Shows which passages were used | Shows the path of entities and edges, too |
| Main failure modes | Missing context, diluted chunks | Extraction errors, duplicate or merged entities, missing edges, stale summaries |
The two are usually combined. Vector search finds where to start in the graph; graph expansion finds what is connected; source passages justify each edge in the final answer.
When should you use Graph RAG?
Use it when a meaningful share of your questions are about relationships: dependency and impact analysis (“what breaks if this service goes down?”), supply-chain and ownership investigations, research literature linking genes, drugs, and diseases, legal and compliance work across many contracts, or "summarize everything we know about X". Stay with vector or hybrid RAG when questions are mostly direct lookups; a graph adds cost there without improving answers. The honest test is to run both on the same labeled questions and compare (see how to evaluate retrieval quality).
Where does Milvus fit in Graph RAG?
Milvus plays the vector-retrieval role in a Graph RAG system. There are two common patterns.
1. Milvus alongside a graph store. Entities, relations, and community reports are embedded and stored in Milvus for “find the right starting nodes” queries, while a graph database or in-memory graph handles traversal. Each Milvus record carries the node or edge ID so results can be handed straight to the traversal step.
2. Graph RAG with only a vector database. Milvus’s Graph RAG tutorial shows that a separate graph database is not strictly required for many multi-hop workloads:
- Three collections hold entities, relations, and passages. Each relation is embedded as a single string, "subject predicate object".
- At query time, the system searches both the entity and relation collections for similarity to the question.
- It expands the hits through the graph using sparse adjacency matrices built in memory from the stored triples (entity-relation adjacency, multiplied to get entity-entity and relation-relation adjacency). Repeated multiplication reaches the desired number of hops.
- An LLM reranks the expanded candidate relations with a chain-of-thought prompt, and the passages linked to the surviving relations become the context.
In the tutorial’s Euler example, naive RAG retrieves the wrong passages, while the expanded subgraph surfaces the passage about Daniel Bernoulli. The approach keeps the stack simple: one database, standard vector search, and graph logic in a few lines of application code.
A minimal schema for pattern 1 or 2 looks like this:
| Collection | Key fields |
|---|---|
entities | entity_id, name, type, description, embedding, source_ids |
relations | relation_id, head_id, relation, tail_id, text (“head relation tail”), embedding, source_ids |
passages | passage_id, doc_id, text, embedding, plus tenant and permission fields |
Use scalar filters on type, tenant, or date to keep traversal inside the right scope, and query by ID (not similarity) when following an edge you already know.
Costs and pitfalls to plan for
- Indexing cost. LLM extraction touches every chunk, and community summarization adds more calls. Estimate it on a sample before indexing the full corpus.
- Extraction quality. Wrong or hallucinated edges become confident wrong answers. Keep a
source_idslink on every entity and relation, and prefer answers that cite the passage behind each hop. - Entity resolution. Under-merging splits one entity into many nodes and breaks paths; over-merging joins unrelated entities. Vector similarity on entity names and descriptions is a good candidate generator for merges, with rules or review deciding.
- Updates. A changed document can invalidate entities, edges, and summaries. Track which graph elements came from which document version so you can re-extract incrementally.
- Access control. Apply permissions to every node and passage reached during traversal, not only to the initial vector search.
- Out-of-the-box quality. Microsoft’s own documentation notes that default prompts may not give the best results and recommends prompt tuning for your domain.
Try it
The fastest way to see the multi-hop effect is to run the Graph RAG with Milvus notebook on its sample data, then on a few hundred of your own documents with ten questions that need two hops. Compare it against a plain baseline built from Build RAG with Milvus, and browse the Milvus Bootcamp for more application starting points. Install Milvus with the Quickstart, or use Zilliz Cloud to skip the setup.
Related reading
- What is retrieval-augmented generation (RAG)?
- What is agentic search, and where does a vector database fit?
- How should an agent choose between vector, keyword, and structured search?
- How can vector search help resolve duplicate or related entities?
- What is reranking, and when should you apply it?


