

Metadata filtering restricts a vector search to records that satisfy structured conditions, such as tenant_id == 42, lang == "en", or published_at > 2025-01-01, and then ranks only those records by vector similarity. Where the filter is applied matters a great deal. Post-filtering (search first, discard non-matching hits afterward) is simple but can return fewer than k results or miss the best eligible ones. Pre-filtering (find eligible records first, then search among them) returns correct results but can be expensive for broad filters. Modern engines, including Milvus, apply the filter during the ANN search so the index only considers eligible records, and back that with scalar indexes and partitioning so the filter itself stays cheap.
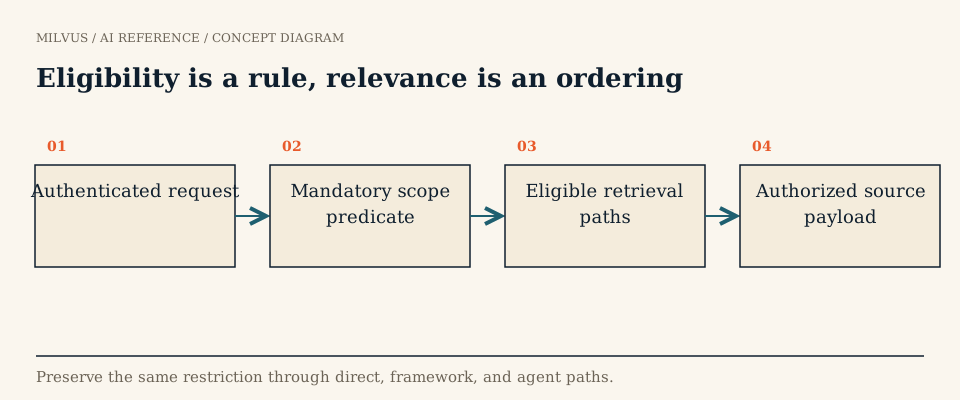 Eligibility is a rule, relevance is an ordering
A useful way to think about it: the filter decides eligibility, and similarity decides order among eligible records. Similarity should never decide whether a user is allowed to see a document or whether a document is current.
Pre-filtering vs post-filtering vs in-search filtering
| Strategy | How it works | Strength | Weakness |
|---|---|---|---|
| Post-filtering | Run top-k ANN on the whole collection, then drop results that fail the filter | Fast and simple; filter cost is tiny | Selective filters leave too few results; eligible neighbors outside the first k are never seen |
| Pre-filtering with brute force | Evaluate the filter, then compute exact distances to every eligible record | Exact and complete | Cost grows with the number of eligible records; slow for broad filters |
| In-search (filtered ANN) | Evaluate the filter into an eligibility set, then traverse the ANN index skipping ineligible records | Correct results at ANN speed across a wide range of selectivities | Very restrictive filters can make graph traversal work harder to find enough neighbors |
Why post-filtering breaks
Suppose a filter matches 1% of the collection and you want 10 results. A plain top-10 search returns, on average, 0.1 eligible results. To expect 10 eligible results you would need to retrieve around 1,000 candidates, and even then the true 10 nearest eligible records might sit at rank 1,500. Raising k helps, but the required k depends on selectivity, which varies per query and per tenant. That is why post-filtering is unsafe for mandatory constraints like tenant isolation, and why it quietly degrades recall for selective business filters.
Why in-search filtering is harder than it looks
Graph indexes such as HNSW are built over all vectors. When a filter removes most nodes, the remaining eligible nodes may be poorly connected, so the search either walks through many ineligible nodes or stops early. Research systems such as ACORN modify HNSW construction and traversal to stay efficient under arbitrary predicates. In practice, engines combine several tactics: brute-force search when very few records qualify, filtered graph traversal when many do, and data layout (partitions) that removes whole regions of data before the search starts.
How filtering works in Milvus
Milvus accepts a boolean filter expression on any search. Fields can be scalars, JSON paths, or arrays, and expressions support comparison (==, !=, <, >=), IN, LIKE, AND/OR/NOT, JSON and array operators, and text-match functions.
results = client.search(
    collection_name="kb",
    data=[query_vector],
    anns_field="embedding",
    limit=10,
    filter='tenant_id == 42 and lang == "en" and published_at > 1735689600',
    output_fields=["title", "published_at"],
)
Standard filtering is the default. Milvus first finds the entities that match the expression, then runs the ANN search restricted to them, and returns the top k. This gives correct, complete results for mandatory constraints.
Iterative filtering is an alternative for very complex or expensive expressions. With search_params={"hints": "iterative_filter"}, Milvus runs the vector search in batches and applies the filter only to the entities it returns, stopping once it has k matches. This reduces how many rows the expression is evaluated on, but because it walks results in sequence it can be slow when few results pass the filter. Use it when the expression is costly and broadly satisfied, not when it is highly selective.
Filter templating lets you write the expression with placeholders and pass values separately. Milvus spends less time parsing large expressions such as long IN lists, and your application no longer has to splice user-supplied values into filter strings:
client.search(
    collection_name="kb",
    data=[query_vector],
    limit=10,
    filter="tenant_id == {tid} and category in {cats}",
    filter_params={"tid": 42, "cats": ["billing", "security"]},
)
Speeding up the filter with scalar indexes
Without an index, Milvus evaluates the expression by scanning field values. Scalar indexes make that lookup fast. Choose by field type and predicate:
| Index | Best for | Notes |
|---|---|---|
INVERTED | Equality and IN on strings and numbers; most general choice | Supports BOOL, integer types, FLOAT, DOUBLE, VARCHAR, JSON paths, and ARRAY |
BITMAP | Low-cardinality fields such as status, region, or flags | Docs suggest cardinality under about 500; not for FLOAT, DOUBLE, JSON, or primary keys |
STL_SORT | Range filters on numeric and TIMESTAMPTZ fields (>, <=, IN) | Sorted values allow binary search for range bounds; cannot be memory-mapped |
NGRAM | LIKE patterns such as title LIKE "%vector%" on VARCHAR or JSON paths | Splits text into n-grams to avoid full scans |
Trie | Prefix lookups on VARCHAR |
Cardinality and skew matter more than the index name. A field with a single dominant value behaves differently from a uniformly distributed one, so measure the conjunctions your application actually sends, not single predicates in isolation. Each index also costs build time, memory, and ingest overhead, so index the fields used in filters on hot paths or for access control, not every column.
Partition keys for tenant and category isolation
If most queries filter on one field, such as tenant, customer, or product line, make it the partition key (is_partition_key=True when adding the field). Milvus hashes records into partitions by that value (16 partitions by default, configurable with num_partitions), and a search whose filter names the key only scans the matching partitions. This turns “filter one tenant out of millions of rows” into "search a small slice", which is both faster and more predictable than filtering a shared index. It also works well for deletes scoped to one key. For deeper design choices, see multi-tenancy for vector search and authentication, RBAC, and tenant filters.
How selectivity affects performance
Selectivity, the fraction of records that pass the filter, is the main performance variable:
- Broad filters (most records pass): close to unfiltered search speed; the filter is cheap if indexed.
- Moderate filters: filtered ANN still works well; check recall against an exact baseline.
- Very selective filters (a tiny fraction passes): only a few vectors qualify, so exact search over them is cheap, but a graph traversal may struggle to find them. A partition key or a filter that prunes whole segments helps most here.
A filter does not universally make search faster or slower. Benchmark with your real distributions, including skewed tenants, rare categories, empty results, and the same limit the application uses.
Testing correctness and quality together
- Correctness: every returned record must satisfy the filter. Create two tenants with near-identical documents and confirm neither ever sees the other’s records, including after reranking and when fetching source text.
- Completeness: compare against an exact baseline (a
FLATindex, same filter and data) to measure filtered Recall@k. See why use a FLAT baseline. - Shortfall behavior: decide what the application does when fewer than k eligible records exist.
- Performance: sweep selectivity on an indexed field while holding vectors and queries fixed, and record p50/p99 latency. A predicate that returns few rows can still be costly if its evaluation path is slow.
Filtering also interacts with sparse and hybrid retrieval; the same eligibility rules should apply to every path, as described in how sparse inverted indexes work. For choosing between vector, keyword, and structured lookups in an agent, see how agents choose retrieval tools.
To try it, load sample data with the Milvus Quickstart and follow the filtered search guide. On managed infrastructure, Zilliz Cloud runs the same filtering and partition-key features without operating the cluster yourself.
Sources and further reading
- Milvus: filtered search (standard and iterative filtering)
- Milvus: basic filter operators
- Milvus: filter templating
- Milvus: index scalar fields
- Milvus: INVERTED index
- Milvus: BITMAP index
- Milvus: STL_SORT index
- Milvus: NGRAM index
- Milvus: use partition key
- Patel et al., ACORN: Performant and Predicate-Agnostic Search Over Vector Embeddings and Structured Data


