

You handle incremental updates in a vector database by giving every indexed record a stable primary key, then applying source changes as upserts (insert-or-replace by key) and deletes, instead of rebuilding the whole index. Change detection usually comes from a content hash, an updated_at watermark, or a change-data-capture stream. In Milvus, new and updated rows are searchable through growing segments almost immediately, deleted rows are filtered out at query time and physically removed later by compaction, and indexes are built in the background as segments seal, so the collection stays online throughout.
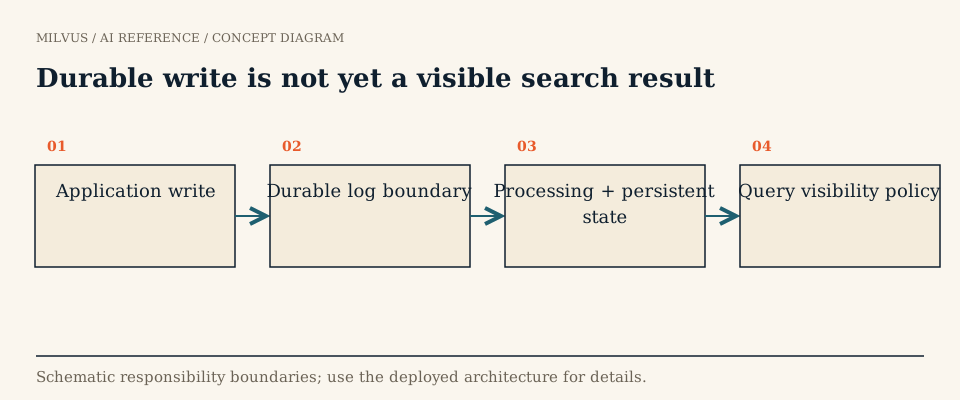 Durable write is not yet a visible search result
Why incremental updates are harder for vectors
A relational row update changes a few bytes in place. A vector record is different in three ways. Its embedding is derived data: if the text changes, the vector must be recomputed by the same model. One source document usually fans out into many chunks, so a single edit can add, change, or remove several rows. And ANN index structures such as HNSW graphs and IVF lists are expensive to modify in place, which is why most vector databases, Milvus included, write changes to new storage and treat deletion as a filter applied until a background rewrite catches up.
Getting this wrong produces familiar RAG bugs: the old and new versions of a policy both appear in results, a deleted document keeps getting cited, or a retried batch doubles every chunk.
Step 1: design keys that make updates idempotent
Everything else depends on identity. Use a deterministic primary key per chunk, for example a hash of source_id + chunk_index, or a VARCHAR key like "kb-1042#3", rather than letting the database assign one. Then a retry writes the same key twice and the second write simply replaces the first. Store alongside each row:
source_id(the parent document) andchunk_indexsource_versionorcontent_hashembedding_modelrevisionupdated_at
Two Milvus behaviors make this important. A plain insert does not check for duplicate primary keys, so inserting an existing key creates a second entity with that key. And with auto_id enabled, upsert still needs the primary key to find the target but assigns a new key to the replacement, which complicates reconciliation. For data that changes, application-defined keys with upsert are the safer default. See stable IDs between lake data and vector search for key design across systems.
Step 2: detect what changed
| Strategy | How it works | Good for |
|---|---|---|
| Content hash | Re-hash each chunk; re-embed only when the hash differs | Periodic syncs of document stores; avoids paying for unchanged embeddings |
| Timestamp watermark | Pull rows with updated_at greater than the last checkpoint | Databases and SaaS APIs with reliable modification times |
| Change data capture | Consume insert/update/delete events from the source log | Low-latency sync from OLTP databases |
| Full snapshot diff | Compare the current source inventory with indexed source_ids | Catching deletions that other methods miss |
Hash comparison is the biggest cost saver because embedding calls dominate pipeline cost. Whatever you choose, run a periodic full diff as well: deletions are the change type incremental feeds most often drop.
Step 3: apply changes with upsert and delete
Changed content. Re-chunk and re-embed the document, then upsert the chunks:
client.upsert(collection_name="kb", data=new_chunks)
In the default override mode, upsert is a delete of the old entity plus an insert of the new one under the same key.
Metadata-only changes. When only a scalar field changes (a status, an ACL tag, a category), Milvus 2.6.2 and later support merge mode, which updates just the supplied fields and keeps the stored vector:
client.upsert(
    collection_name="kb",
    data=[{"id": "kb-1042#3", "status": "archived"}],
    partial_update=True,
)
Shrinking documents. If a document went from 12 chunks to 9, upserting chunks 0 to 8 leaves 9 to 11 behind. Delete the leftovers by expression:
client.delete(
    collection_name="kb",
    filter='source_id == "kb-1042" and source_version < 7',
)
A simple robust pattern for document replacement is: upsert the new version’s chunks with the new source_version, then delete everything for that source_id with an older version.
Deleted documents. Delete by source_id filter or by primary-key list (ids=[...]). Add partition_name to scope the operation when data is partitioned. The lake deletion guide covers propagation from upstream tables.
What happens inside Milvus after an update?
New and upserted rows go to growing segments, which are searchable before the full vector index has been built for them. When a growing segment fills, it is sealed, and Data Nodes build the vector index on it and run compaction, which merges small segments and physically drops rows that were deleted. Until compaction runs, deleted rows are tracked and filtered out of results, so they do not appear in search, but they still occupy storage. That is why heavy update or delete churn shows up as extra disk and memory until compaction catches up, and why you do not need to trigger index rebuilds yourself for routine updates.
When will the update be visible?
Visibility is controlled by the consistency level. Milvus offers Strong, Bounded staleness (the default), Session, and Eventually. Under Bounded staleness, a search issued right after an upsert may briefly miss it. If a user edits a document and immediately searches for it, use Session consistency for that client or Strong for that request. For bulk background syncs, Bounded is usually fine and cheaper.
Re-embedding with a new model is a migration, not an update
Vectors from two embedding models are not comparable, so you cannot upgrade the model row by row inside one vector field and keep searching it. Instead, build a new collection for the new model (or fill a second vector field that you defined in the schema up front), backfill it (bulk import is fastest for this), evaluate recall on a fixed query set, switch reads over, and then retire the old collection. A collection alias makes the switch a single atomic pointer change for applications. Embedding pipeline design covers the backfill side.
Handle ordering, retries, and drift
- Out-of-order events: if a late event carries an older
source_version, skip it rather than overwriting newer data. Do this check in the ingestion worker, since upsert itself is last-write-wins. - Ambiguous failures: if an upsert times out, retry it. Deterministic keys make retries safe, while auto-generated keys would create duplicates.
- Reconciliation: periodically compare source counts and versions with what
query(filter='source_id == ...')returns, and alert on drift. Track ingestion lag as a first-class metric so a missing answer can be traced to “not yet indexed” rather than “not in the corpus.”
Next step
Try the full lifecycle in a test collection: insert a document, upsert a shorter revision, delete leftovers by version, and search under Session consistency to confirm what is visible. The Quickstart gets a local instance running in minutes, and Zilliz Cloud runs the same operations as a managed service. Related reading: how ETL prepares data for vector search and refreshing Milvus external collections.


