

Keyword search finds documents that contain the query’s words, using an inverted index and a scoring function such as BM25. Semantic search finds documents whose meaning is close to the query’s, by turning text into embedding vectors and searching for nearest neighbors. Keyword search is precise for exact terms like error codes, names, and version numbers but misses synonyms and paraphrases; semantic search handles paraphrases and natural-language questions but can blur exact identifiers. Most production systems run both and merge the results, which is called hybrid search.
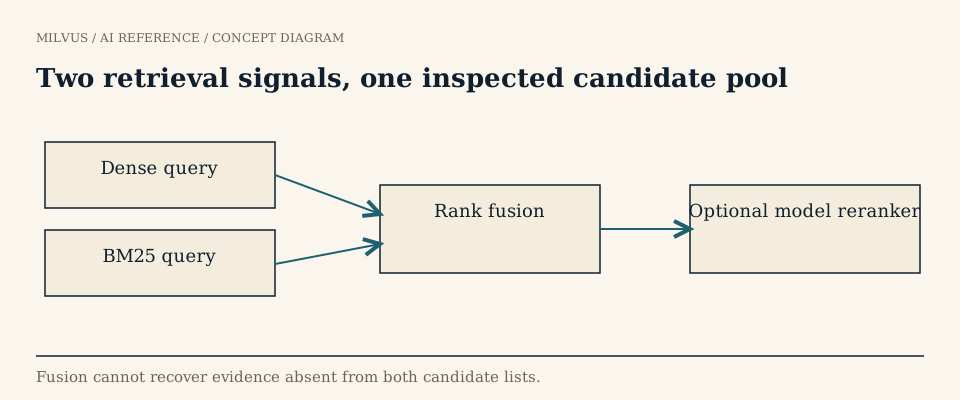 Two retrieval signals, one inspected candidate pool
Semantic vs keyword search at a glance
| Keyword (lexical) search | Semantic (vector) search | |
|---|---|---|
| What is matched | Analyzed terms (tokens) shared by query and document | Proximity of embedding vectors |
| Index | Inverted index: term → list of documents | ANN index such as HNSW or IVF over dense vectors |
| Typical scoring | BM25 or TF-IDF | Cosine similarity, inner product, or L2 distance |
| Handles synonyms and paraphrase | Poorly, unless you add synonym lists | Well |
| Exact codes, SKUs, rare names | Strong | Often weak |
| Cross-language matching | No | Yes, with a multilingual model |
| Explainability | High: you can see which terms matched | Low: similarity is a learned geometry |
| Needs an ML model | No | Yes, at ingest and at query time |
| Main failure mode | Vocabulary mismatch | Plausible but wrong neighbors |
How does keyword search work?
Before indexing, an analyzer turns raw text into tokens. It splits on whitespace and punctuation, lowercases, and may remove stop words or reduce words to a stem, so “Indexes” and “indexing” can map to the same term. The index then stores, for each term, the list of documents that contain it (a posting list). A query is analyzed the same way, the posting lists for its terms are read, and candidate documents are scored.
BM25, the standard scoring function, rewards three things: a term appearing more often in the document (with diminishing returns controlled by k1), a term being rare across the corpus (inverse document frequency), and the document not being excessively long (length normalization controlled by b). A document can rank highly while missing some query words, so BM25 is a ranking, not a guarantee that every term is present. When a condition must hold exactly, such as "the passage must contain this error code", use a filter rather than hoping the score enforces it.
Keyword search fails when the user and the author choose different words. A query for “stop the service from restarting by itself” will not match a runbook that says “disable automatic failover” unless the words overlap.
How does semantic search work?
An embedding model maps each document (or chunk) to a dense vector of a few hundred to a few thousand numbers, trained so that texts with similar meaning land near each other. At query time the query is embedded with the same model, and an approximate nearest-neighbor index returns the closest vectors. The runbook example above works here, because “restarting by itself” and “automatic failover” sit close together in a well-trained embedding space. For more on how those vectors are produced, see what are embeddings.
Semantic search has its own blind spots. Embedding models compress meaning, and strings like E-1042, v2.6.3, or a part number carry little semantic signal, so the nearest vectors may be documents about similar errors rather than the exact one. Negation (“without GPU”), numeric constraints, and very rare domain terms that the model never saw in training are also weak spots. And every result looks plausible, which makes wrong answers harder to spot than a keyword miss.
When should you use each?
Keyword search fits when queries are short and exact: product codes, ticket IDs, function names, legal citations, log messages, and any domain where users type the literal string they expect to see. It is also the simpler option when you need deterministic, explainable results or cannot run an embedding model.
Semantic search fits when users ask questions in natural language, when documents and queries use different vocabulary, when you need cross-language retrieval, and in RAG pipelines where the goal is “find passages that answer this question” rather than “find passages that contain these words.”
Hybrid search fits most real applications, because real query logs mix both kinds. A support search box receives “E-1042 after upgrade” and “why does my index keep returning old results” on the same day.
How hybrid search combines them
Hybrid retrieval runs a keyword path and a vector path in parallel over the same documents, applies the same access and metadata filters to both, and merges the two candidate lists. The usual merge is Reciprocal Rank Fusion (RRF), which scores each document by 1 / (k + rank) summed across the lists and ignores raw scores that are not comparable across methods. A weighted score blend is the alternative when you have evaluation data to tune the weights. A reranker can then reorder the fused list; see what is reranking.
Fusion only reorders what the two paths found. If neither path retrieves a relevant document, no ranker can recover it, so check candidate recall for each path before tuning the merge. For a deeper look, see what is hybrid search.
Doing both in Milvus
Milvus supports keyword and semantic search in one collection.
- BM25 full-text search. Define a
VARCHAR(orTEXT) field withenable_analyzer=True, aSPARSE_FLOAT_VECTORfield, and aFunctionof typeFunctionType.BM25that converts text into sparse vectors at insert time. Index the sparse field withSPARSE_INVERTED_INDEXandmetric_type="BM25", then search with raw query text. The default analyzer isstandard, and you can configure others per language. - Exact term and phrase filters. With
enable_match=Trueon the text field, filter expressions likeTEXT_MATCH(text, 'failover')andPHRASE_MATCH(text, 'automatic failover', 1)restrict results to documents containing those terms or that phrase (withslopcontrolling allowed gaps). These are Boolean filters, not relevance scores. - Dense vector search. A
FLOAT_VECTORfield indexed withHNSW,IVF_FLAT, or another vector index, queried with an embedding of the user’s question. - Hybrid search.
hybrid_search()runs oneAnnSearchRequestper path and merges them with an RRF or weighted ranker.
from pymilvus import AnnSearchRequest, Function, FunctionType

dense_req = AnnSearchRequest(data=[query_embedding], anns_field="dense",
                             param={}, limit=50)
bm25_req = AnnSearchRequest(data=["E-1042 after upgrade"], anns_field="sparse",
                            param={}, limit=50)   # raw text; BM25 function embeds it

rrf = Function(name="rrf", input_field_names=[],
               function_type=FunctionType.RERANK,
               params={"reranker": "rrf", "k": 60})

results = client.hybrid_search(collection_name="support_docs",
                               reqs=[dense_req, bm25_req],
                               ranker=rrf, limit=10, output_fields=["text"])
How to decide from your own queries
Pull a few hundred real queries and label them: exact-identifier lookups, paraphrased questions, mixed queries, and queries with no valid answer. Run keyword-only, dense-only, and hybrid retrieval over the same documents with the same filters and the same final limit, and judge the top results. Look at each path’s candidate list before fusion to see which one carries each query type. Keep the second path if it adds relevant results often enough to justify the extra index, ingest time, and latency. The retrieval evaluation guide describes the metrics.
To try this hands-on, start with the Milvus Quickstart, then follow the full-text search guide to add a BM25 field next to your dense vectors. Related reading: full-text search and BM25 and dense vs sparse embeddings.



