

创建外部CollectionCompatible with Milvus 3.0.x
外部 Collection 是 Milvus 中的一种数据 Collection,它可直接访问来自外部存储系统或数据库表(如 AWS S3 和 Iceberg)的数据,而无需将数据复制到 Milvus 中。它作为数据湖上的查询层,同时保持与 Milvus 查询接口的兼容性。
此功能需要 Storage V3 支持。有关启用说明和兼容性注意事项,请参阅Storage V3。
概述
在典型的 AI 数据管道中,用户可能已将数据以 Parquet 或其他格式存储在存储系统(如 AWS S3)中。为了让 Milvus 能够使用这些外部存储的数据,用户通常需要通过提取-转换-加载(ETL)管道将其导入 Milvus 的自有存储中。
这种“将数据带入 Milvus”的工作流会产生难以同步的冗余数据,并增加了确保数据一致性所需的工程维护负担。
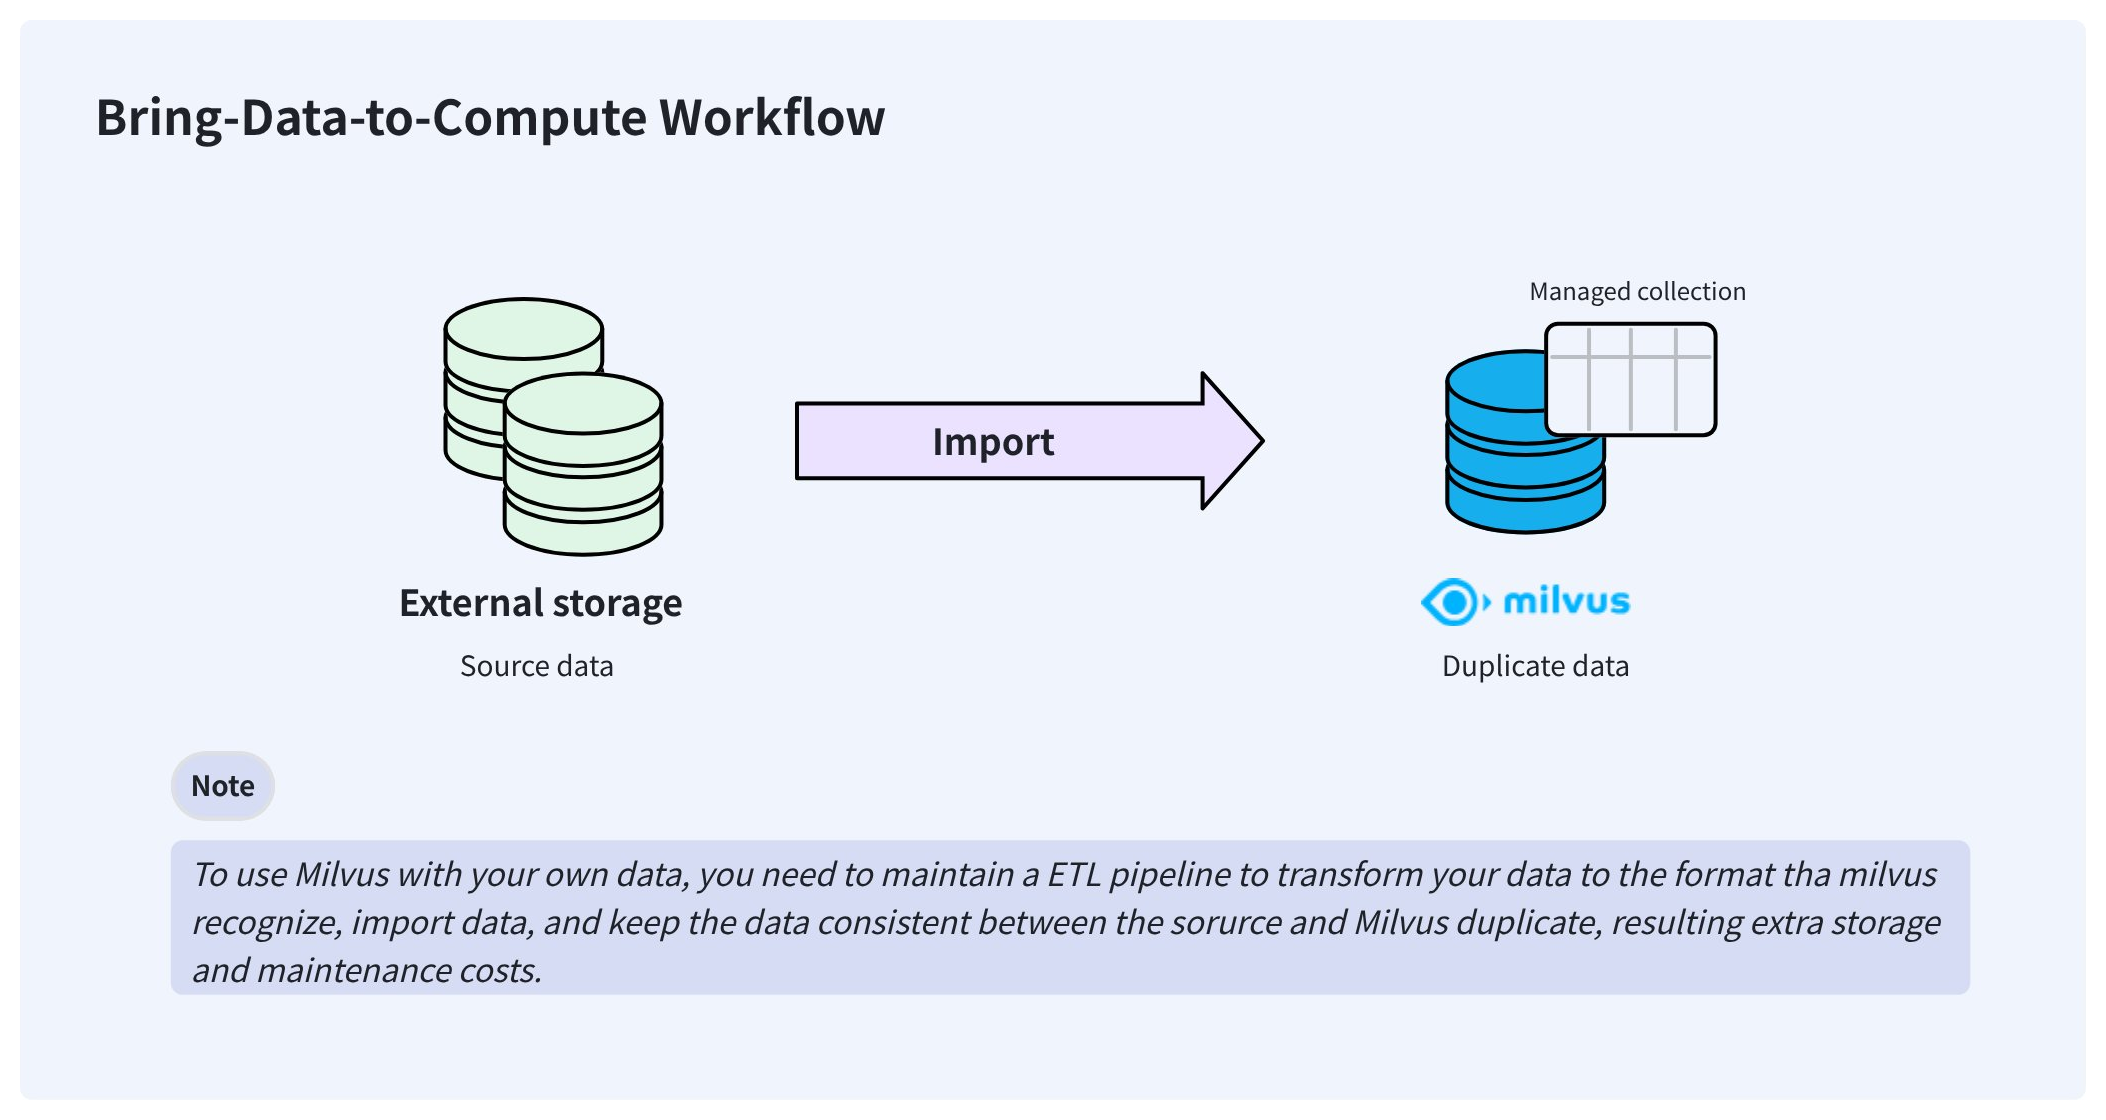 将数据引入计算工作流
为解决这些问题,Milvus 提供了外部 Collections 功能,让您能够直接从 Milvus 访问外部存储的数据,无需担心数据同步和 ETL 管道的问题。
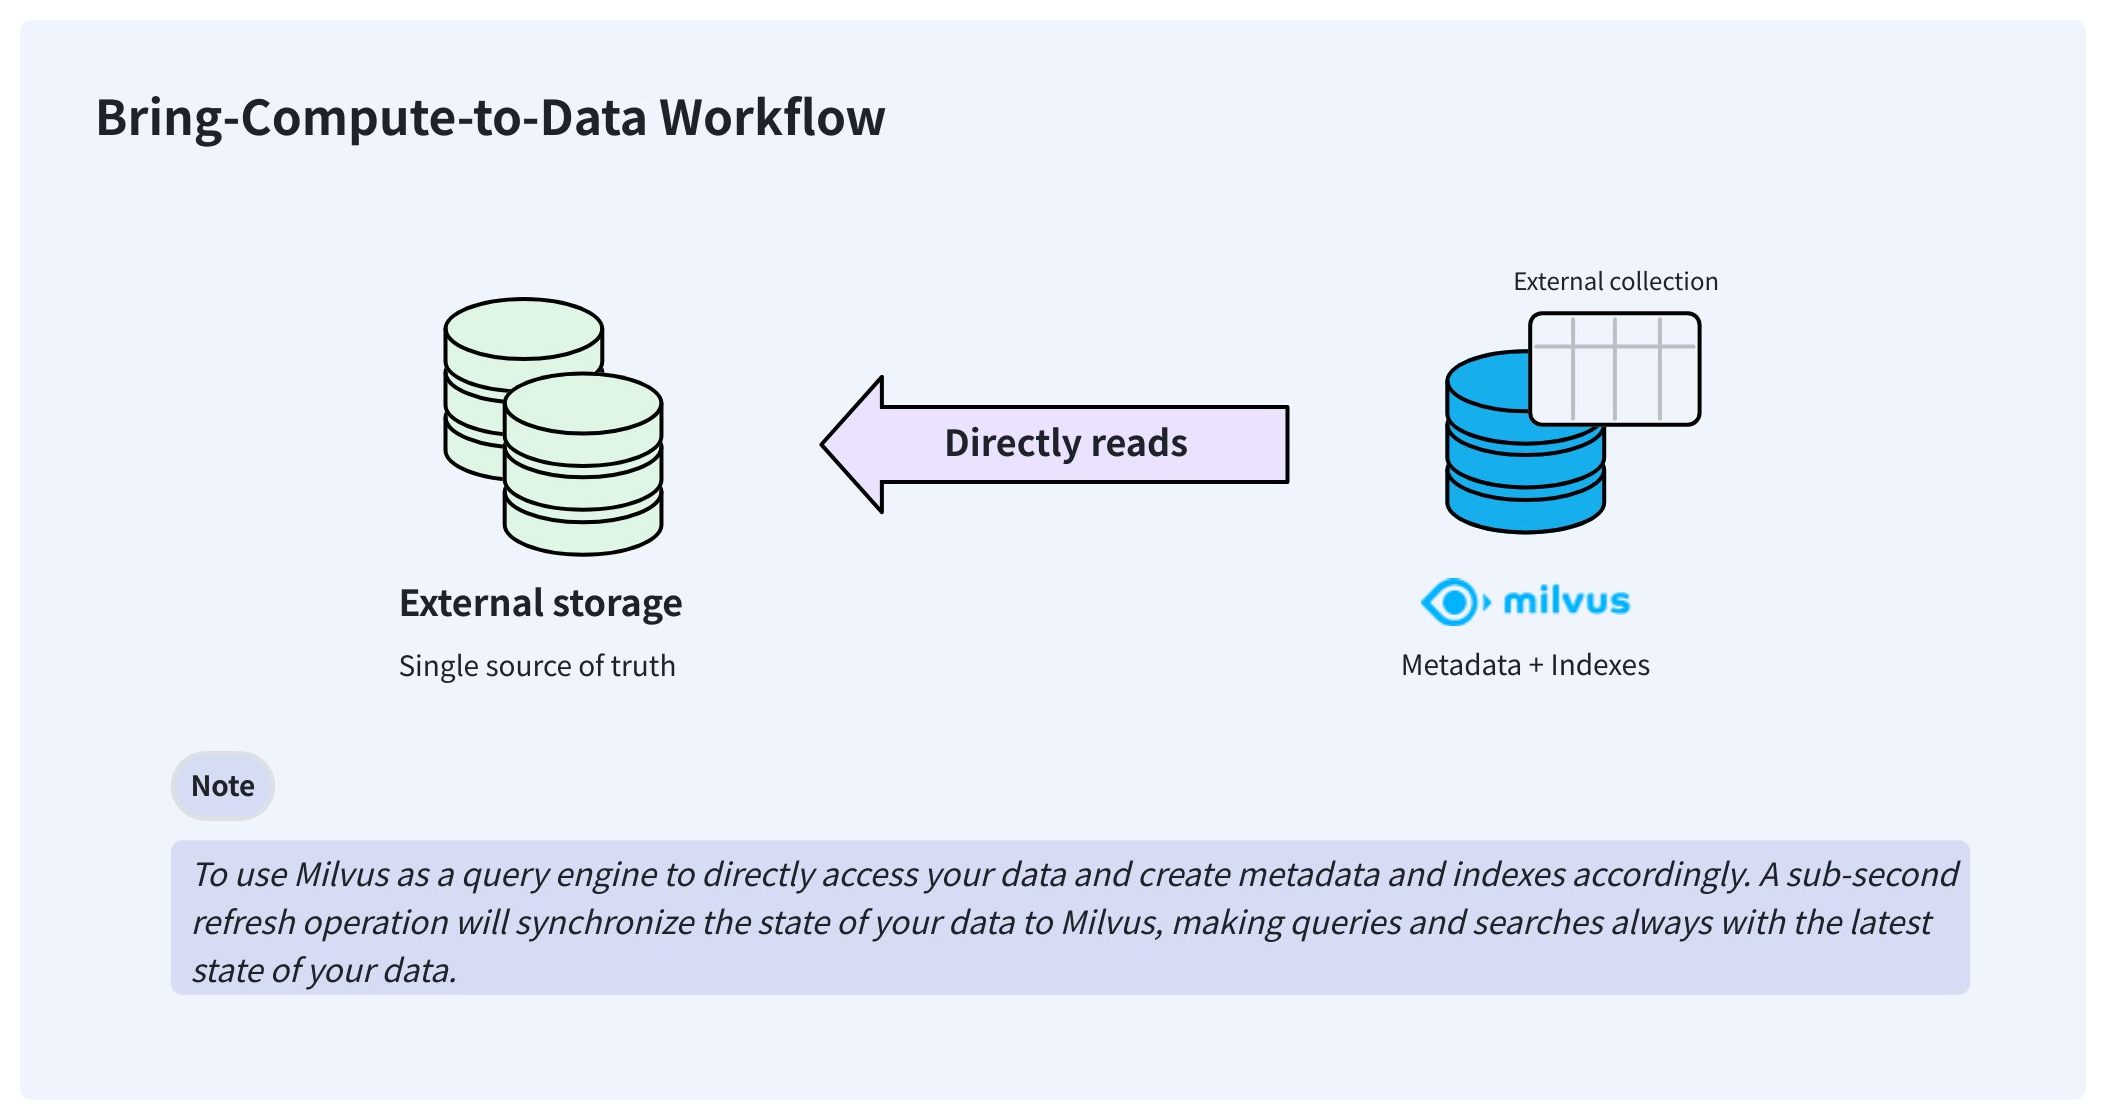 “将计算带到数据”工作流
外部 Collection 创建后,即可直接访问您的数据,并将数据保留在您存储的原始位置。在后台,Milvus 会生成清单文件,用于记录 Milvus 元数据与外部数据文件中各行之间的映射关系。清单文件准备就绪后,您就可以像在任何托管 Collection 中一样,在外部 Collection 中创建索引。
当数据发生变化时,手动触发亚秒级刷新即可更新元数据,确保 Milvus 始终保持最新状态。
步骤 1:创建 Schema
与创建托管 Collection 一样,在创建外部 Collection 之前,您也需要先创建 Schema。不过,该 Schema 与托管 Collection 的 Schema 略有不同。
from pymilvus import MilvusClient, DataType

schema = MilvusClient.create_schema(
    external_source='s3://s3.<region-id>.amazonaws.com/<bucket>/',
    external_spec='{
        "format": "parquet",
        "extfs": {
            ...
        }
    }'
)
import com.google.gson.JsonObject;
import io.milvus.v2.service.collection.request.CreateCollectionReq;

JsonObject externalSpec = new JsonObject();
externalSpec.addProperty("format", "parquet");
externalSpec.add("extfs", new JsonObject());

CreateCollectionReq.CollectionSchema schema = CreateCollectionReq.CollectionSchema.builder()
        .externalSource("s3://s3.<region-id>.amazonaws.com/<bucket>/")
        .externalSpec(externalSpec)
        .build();
import (
    "github.com/milvus-io/milvus/client/v2/entity"
    client "github.com/milvus-io/milvus/client/v2/milvusclient"
)

schema := entity.NewSchema().
    WithName("product_embeddings").
    WithExternalSource("s3://my-bucket/embeddings/").
    WithExternalSpec(`{"format": "parquet", "extfs": { ... }}`)
// node
export fields='[
        {
            "fieldName": "product_id",
            "dataType": "Int64",
            "isPrimary": true
        },
        {
            "fieldName": "embedding",
            "dataType": "FloatVector",
            "elementTypeParams": {
                "dim": "768"
            }
        },
        {
            "fieldName": "product_name",
            "dataType": "VarChar",
            "elementTypeParams": {
                "max_length": 512
            }
        }
    ]'
要为外部Collection创建Schema,您需要指定源数据 URI、数据格式以及身份验证设置。
参数名称 |
参数描述 |
示例值 |
|---|---|---|
|
目标源数据文件的格式。 |
|
|
一个有效的 Iceberg 表快照 ID。此参数仅在将 ` |
|
|
以字符串形式的 JSON 结构表示的外部文件系统设置。 |
-- |
您可以通过以下选项设置身份验证设置:
使用 AWS 访问密钥/安全密钥
此选项适用于自托管的 MinIO,或您已拥有用于工作的 AK/SK 的场景。
{
    "format": "...",
    "extfs": {
        "access_key_id":     "AKIA..",
        "access_key_value":  "u4Lh...",
        "region":            "us-west-2",
        "cloud_provider":    "aws",
        "use_ssl":           "true",
        "use_virtual_host":  "true"
    }
}
参数名称 |
参数说明 |
示例值 |
|---|---|---|
|
访问密钥 ID |
|
|
访问密钥值 |
|
|
云区域 ID |
|
|
云服务提供商 ID |
|
|
是否使用 SSL 建立连接。 |
|
|
是否使用虚拟托管访问您的存储桶。 有关详细信息,请参阅这篇文章。 |
|
使用 AWS IAM
此选项适用于 Milvus 在 EC2 实例或 EKS 集群上运行的场景。在此情况下,您无需硬编码 AK/SK。
{
    "format": "...",
    "extfs": {
        "use_iam":           "true",
        "iam_endpoint":      "https://sts.<region>.amazonaws.com",
        "region":            "us-west-2",
        "cloud_provider":    "aws",
        "use_ssl":           "true"
    }
}
参数名称 |
参数 描述 |
示例值 |
|---|---|---|
|
是否使用 AWS IAM。 对于此选项,请将其设置为 |
|
|
一个有效的 AWS STS 端点。 有关详细信息,请参阅本文。 |
|
|
云区域 ID |
|
|
云提供商 ID |
|
|
是否使用 SSL 建立连接。 |
|
使用 Milvus 全局凭据
当您将外部数据存储在 Milvus 存储桶中时,此选项适用,且可直接使用milvus.yaml 中指定的全局 MinIO 设置来访问数据。
{
    "format": "...",
    "extfs": {
        "storage_type": "remote"
    }
}
使用 IAM 角色 ARN
当您的组织使用不同的 AWS 账户来管理 Milvus 集群和存储目标数据文件的存储桶时,应使用此选项。
在这种情况下,存储桶所有者应创建一个 IAM 角色,该角色
该角色应绑定
AmazonS3FullAccess或更精细的存储桶访问策略。在角色的“信任策略”的“条件”字段中包含一个自定义的
sts:ExternalId。
随后,存储桶所有者应向您提供该 IAM 角色的 ARN 和外部 ID,以便您使用这些值调用 `sts:AssumeRole ` 来承接该 IAM 角色。
以下是一个示例权限策略,可附加到 IAM 角色上并包含允许的权限。您可以根据需求进行调整。
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": [
                "s3:ListBucket",
                "s3:GetBucketLocation"
            ],
            "Resource": "arn:aws:s3:::SOURCE-DATA-BUCKET"
        },
        {
            "Effect": "Allow",
            "Action": [
                "s3:GetObject",
                "s3:PutObject",
                "s3:DeleteObject"
            ],
            "Resource": "arn:aws:s3:::SOURCE-DATA-BUCKET/*"
        }
    ]
}
此外,与该 IAM 角色关联的信任策略定义了谁被允许承担该角色。
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Principal": {
        "AWS": "arn:aws:iam::ACCOUNT_RUNNING_MILVUS:root"
      },
      "Action": "sts:AssumeRole",
      "Condition": {
        "StringEquals": {
          "sts:ExternalId": "YOUR_UNIQUE_EXTERNAL_ID"
        }
      }
    }
  ]
}
获取 IAM 角色 ARN 和外部 ID 后,您可以按以下方式设置external_spec 参数:
{
    "format": "...",
    "extfs": {
        "cloud_provider": "aws",
        "region": "us-west-2",
        "storage_type": "remote",
        "use_ssl": "true",
        "use_iam": "true",
        "role_arn": "arn:aws:iam::306787000000:role/lentitude-bucket-role",
        "external_id": "YOUR_UNIQUE_EXTERNAL_ID",
        "load_frequency": "900"
    }
}
参数名称 |
参数描述 |
示例值 |
|---|---|---|
|
云服务提供商 ID |
|
|
云区域 ID |
|
|
是否使用 SSL 建立连接。 |
|
|
是否使用 AWS IAM。 请将此选项设置为 |
|
|
从存储桶所有者处获取的 IAM 角色 ARN。 |
|
|
从存储桶所有者处获取的外部 ID。 |
-- |
|
Milvus 获取临时身份验证凭据的间隔(单位:秒)。 |
|
步骤 2:添加字段
准备好Schema后,您可以按以下方式添加字段:
schema.add_field(
    field_name="product_id",
    datatype=DataType.INT64,
    external_field="id" # field name in the external data file
)
schema.add_field(
    field_name="product_name",
    datatype=DataType.VARCHAR,
    max_length=512,
    external_field="name"
)
schema.add_field(
    field_name="embedding",
    datatype=DataType.FLOAT_VECTOR,
    dim=768,
    external_field="vector"
)
import io.milvus.v2.common.DataType;
import io.milvus.v2.service.collection.request.AddFieldReq;

schema.addField(AddFieldReq.builder()
        .fieldName("product_id")
        .dataType(DataType.Int64)
        .externalField("id")
        .build());
schema.addField(AddFieldReq.builder()
        .fieldName("product_name")
        .dataType(DataType.VarChar)
        .maxLength(512)
        .externalField("name")
        .build());
schema.addField(AddFieldReq.builder()
        .fieldName("embedding")
        .dataType(DataType.FloatVector)
        .dimension(768)
        .externalField("vector")
        .build());
import (
    "github.com/milvus-io/milvus/client/v2/entity"
    client "github.com/milvus-io/milvus/client/v2/milvusclient"
)

schema = schema.
    WithField(
        entity.NewField().
            WithName("product_id").
            WithDataType(entity.FieldTypeInt64).
            WithExternalField("id"),
    ).
    WithField(
        entity.NewField().
            WithName("product_name").
            WithDataType(entity.FieldTypeVarChar).
            WithMaxLength(512).
            WithExternalField("name"),
    ).
    WithField(
        entity.NewField().
            WithName("embedding").
            WithDataType(entity.FieldTypeFloatVector).
            WithDim(768).
            WithExternalField("vector"),
    )
// node
export schema="{
    \"externalSource\": \"volume://my_volume/path/to/a/folder\",
    \"externalSpec\": \"{\\\"format\\\": \\\"parquet\\\"}\",
    \"fields\": $fields
}"
步骤 3:创建 Collection
将所有字段添加到Schema后,即可创建外部Collection。
client = MilvusClient(
    uri="http://localhost:19530",
    token="root:Milvus"
)

client.create_collection(
    collection_name="test_collection",
    schema=schema
)
import io.milvus.v2.client.ConnectConfig;
import io.milvus.v2.client.MilvusClientV2;

ConnectConfig connectConfig = ConnectConfig.builder()
        .uri("http://localhost:19530")
        .token("root:Milvus")
        .build();

MilvusClientV2 client = new MilvusClientV2(connectConfig);

CreateCollectionReq createReq = CreateCollectionReq.builder()
        .collectionName("test_collection")
        .collectionSchema(schema)
        .build();
client.createCollection(createReq);
import (
    "github.com/milvus-io/milvus/client/v2/entity"
    client "github.com/milvus-io/milvus/client/v2/milvusclient"
)

ctx, cancel := context.WithCancel(context.Background())
defer cancel()

milvusAddr := "http://localhost:19530"
token := "root:Milvus"

client, err := milvusclient.New(ctx, &milvusclient.ClientConfig{
    Address: milvusAddr,
    APIKey: token
})

err = client.CreateCollection(ctx, milvusclient.NewCreateCollectionOption("test_collection", schema))

if err != nil {
    fmt.Println(err.Error())
    // handle error
}
// node
curl --request POST \
--url "${PROJECT_ENDPOINT}/v2/vectordb/collections/create" \
--header "Authorization: Bearer ${TOKEN}" \
--header "Content-Type: application/json" \
--header "Request-Timeout: 10" \
-d "{
    \"dbName\": \"my_database\",
    \"collectionName\": \"test_collection\",
    \"schema\": $schema
}"
步骤 4:创建索引
您可以像在管理 Collections 中一样,为外部 Collection 字段创建索引。
index_params = client.prepare_index_params()
# Add indexes
index_params.add_index(
    field_name="embedding",
    index_type="AUTOINDEX",
    metric_type="COSINE"
)
index_params.add_index(
    field_name="product_name",
    index_type="AUTOINDEX"
)
client.create_index(
    db_name="my_database",
    collection_name="test_collection",
    index_params=index_params
)
import io.milvus.v2.common.IndexParam;
import io.milvus.v2.service.index.request.CreateIndexReq;
import java.util.*;

IndexParam indexParamForIdField = IndexParam.builder()
        .fieldName("product_name")
        .indexType(IndexParam.IndexType.AUTOINDEX)
        .build();
IndexParam indexParamForVectorField = IndexParam.builder()
        .fieldName("embedding")
        .indexType(IndexParam.IndexType.AUTOINDEX)
        .metricType(IndexParam.MetricType.COSINE)
        .build();
List<IndexParam> indexParams = new ArrayList<>();
indexParams.add(indexParamForIdField);
indexParams.add(indexParamForVectorField);
CreateIndexReq createIndexReq = CreateIndexReq.builder()
        .dbName("my_database")
        .collectionName("test_collection")
        .indexParams(indexParams)
        .build();
client.createIndex(createIndexReq);
import (
    "github.com/milvus-io/milvus/client/v2/entity"
    "github.com/milvus-io/milvus/client/v2/index"
    "github.com/milvus-io/milvus/client/v2/milvusclient"
)

collectionName := "test_collection"
indexOptions := []milvusclient.CreateIndexOption{
    milvusclient.NewCreateIndexOption(collectionName, "embedding", index.NewAutoIndex(entity.COSINE)),
    milvusclient.NewCreateIndexOption(collectionName, "product_name", index.NewAutoIndex(index.AUTOINDEX)),
}
indexTask, err := client.CreateIndex(ctx, indexOptions)
if err != nil {
    // handler err
}
err = indexTask.Await(ctx)
if err != nil {
    // handler err
}
client.createIndex({
    db_name: "my_database",
    collection_name: "test_collection",
    field_name: "product_name",
    index_type: "AUTOINDEX"
})
client.createIndex({
    db_name: "my_database",
    collection_name: "test_collection",
    field_name: "embedding",
    index_type: "AUTOINDEX",
    metric_type: "COSINE"
})
export indexParams='[
        {
            "fieldName": "embedding",
            "indexName": "my_vector",
            "indexType": "AUTOINDEX"
        },
        {
            "fieldName": "product_name",
            "indexName": "my_id",
            "indexType": "AUTOINDEX"
        }
    ]'

curl --request POST \
--url "${PROJECT_ENDPOINT}/v2/vectordb/indexes/create" \
--header "Authorization: Bearer ${TOKEN}" \
--header "Content-Type: application/json" \
--header "Request-Timeout: 10" \
-d "{
    \"dbName\": \"my_database\",
    \"collectionName\": \"test_collection\",
    \"indexParams\": $indexParams
}"
步骤 5:刷新数据
Collection准备就绪后,请刷新该Collection以生成数据的元数据和索引。
job_id = client.refresh_external_collection(
    db_name="my_database",
    collection_name="test_collection"
)
while True:
    progress = client.get_refresh_external_collection_progress(job_id=job_id)
    print(f"  {progress.state}: {progress.progress}%")
    if progress.state == "RefreshCompleted":
        elapsed = progress.end_time - progress.start_time
        print(f"  Completed in {elapsed}ms")
        break
    elif progress.state == "RefreshFailed":
        print(f"  Failed: {progress.reason}")
        break
    time.sleep(2)
import io.milvus.v2.service.utility.request.GetRefreshExternalCollectionProgressReq;
import io.milvus.v2.service.utility.request.ListRefreshExternalCollectionJobsReq;
import io.milvus.v2.service.utility.request.RefreshExternalCollectionReq;
import io.milvus.v2.service.utility.response.GetRefreshExternalCollectionProgressResp;
import io.milvus.v2.service.utility.response.ListRefreshExternalCollectionJobsResp;
import io.milvus.v2.service.utility.response.RefreshExternalCollectionJobInfo;
import io.milvus.v2.service.utility.response.RefreshExternalCollectionResp;

while (true) {
    GetRefreshExternalCollectionProgressResp resp = client.getRefreshExternalCollectionProgress(
            GetRefreshExternalCollectionProgressReq.builder()
                    .jobId(jobId)
                    .build());
    RefreshExternalCollectionJobInfo jobInfo = resp.getJobInfo();
    if ("RefreshCompleted".equals(jobInfo.getState())) {
        long elapsed = jobInfo.getEndTime() - jobInfo.getStartTime();
        System.out.printf("  Refresh completed in %dms%n", elapsed);
        break;
    } else if ("RefreshFailed".equals(jobInfo.getState())) {
        System.out.printf("  Refresh failed: %s%n", jobInfo.getReason());
    }
    TimeUnit.SECONDS.sleep(2);
}
refreshResult, err := client.RefreshExternalCollection(ctx,
    client.NewRefreshExternalCollectionOption("test_collection"))
jobID := refreshResult.JobID
for {
    progress, _ := client.GetRefreshExternalCollectionProgress(ctx,
        client.NewGetRefreshExternalCollectionProgressOption(jobID))
    fmt.Printf("State: %s\n", progress.State)
    if progress.State == entity.RefreshStateCompleted {
        fmt.Println("Refresh completed!")
        break
    }
    if progress.State == entity.RefreshStateFailed {
        fmt.Printf("Refresh failed: %s\n", progress.Reason)
        break
    }
    time.Sleep(2 * time.Second)
}
// node
curl --request POST \
--url "${PROJECT_ENDPOINT}/v2/vectordb/jobs/external_collection/refresh" \
--header "Authorization: Bearer ${TOKEN}" \
--header "Content-Type: application/json" \
--header "Request-Timeout: 10" \
-d "{
    \"dbName\": \"my_database\",
    \"collectionName\": \"test_collection\",
    \"externalSource\": \"volume://my_volume/path/to/a/folder\",
    \"externalSpec\": \"{\\\"format\\\": \\\"parquet\\\"}\"
}"
刷新操作是异步的,因此您需要设置一个循环来监控其进度。
刷新操作会扫描数据文件的元数据,并据此生成清单文件。该过程通常需要 150-250 毫秒。
清单文件记录了 Milvus 中的元数据与外部文件中行之间的映射关系。
如果源数据发生更新,您需要手动再次调用刷新操作,以保持 Milvus 的数据最新。
如果刷新操作需要删除所有活跃元数据且不插入任何新数据,则该操作将被拒绝。
后续步骤
刷新外部集合后,您可以加载和释放该 Collection,并在外部 Collection 中执行相似度搜索和查询,就像在任何托管 Collection 中一样,但需注意:用于按需计算的数据库中的 Collection 必须附加到按需集群上才能进行搜索和查询。
在执行 DQL 操作(如搜索、查询、获取和混合搜索)之前,您需要创建一个会话以挂载按需计算集群的计算资源。
如果外部数据源后续包含另一个您希望在 Milvus 中暴露的字段,请向外部 Collection Schema 添加该字段,并再次刷新外部 Collection。有关详细信息,请参阅《修改外部 Collection Schema》。
